Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
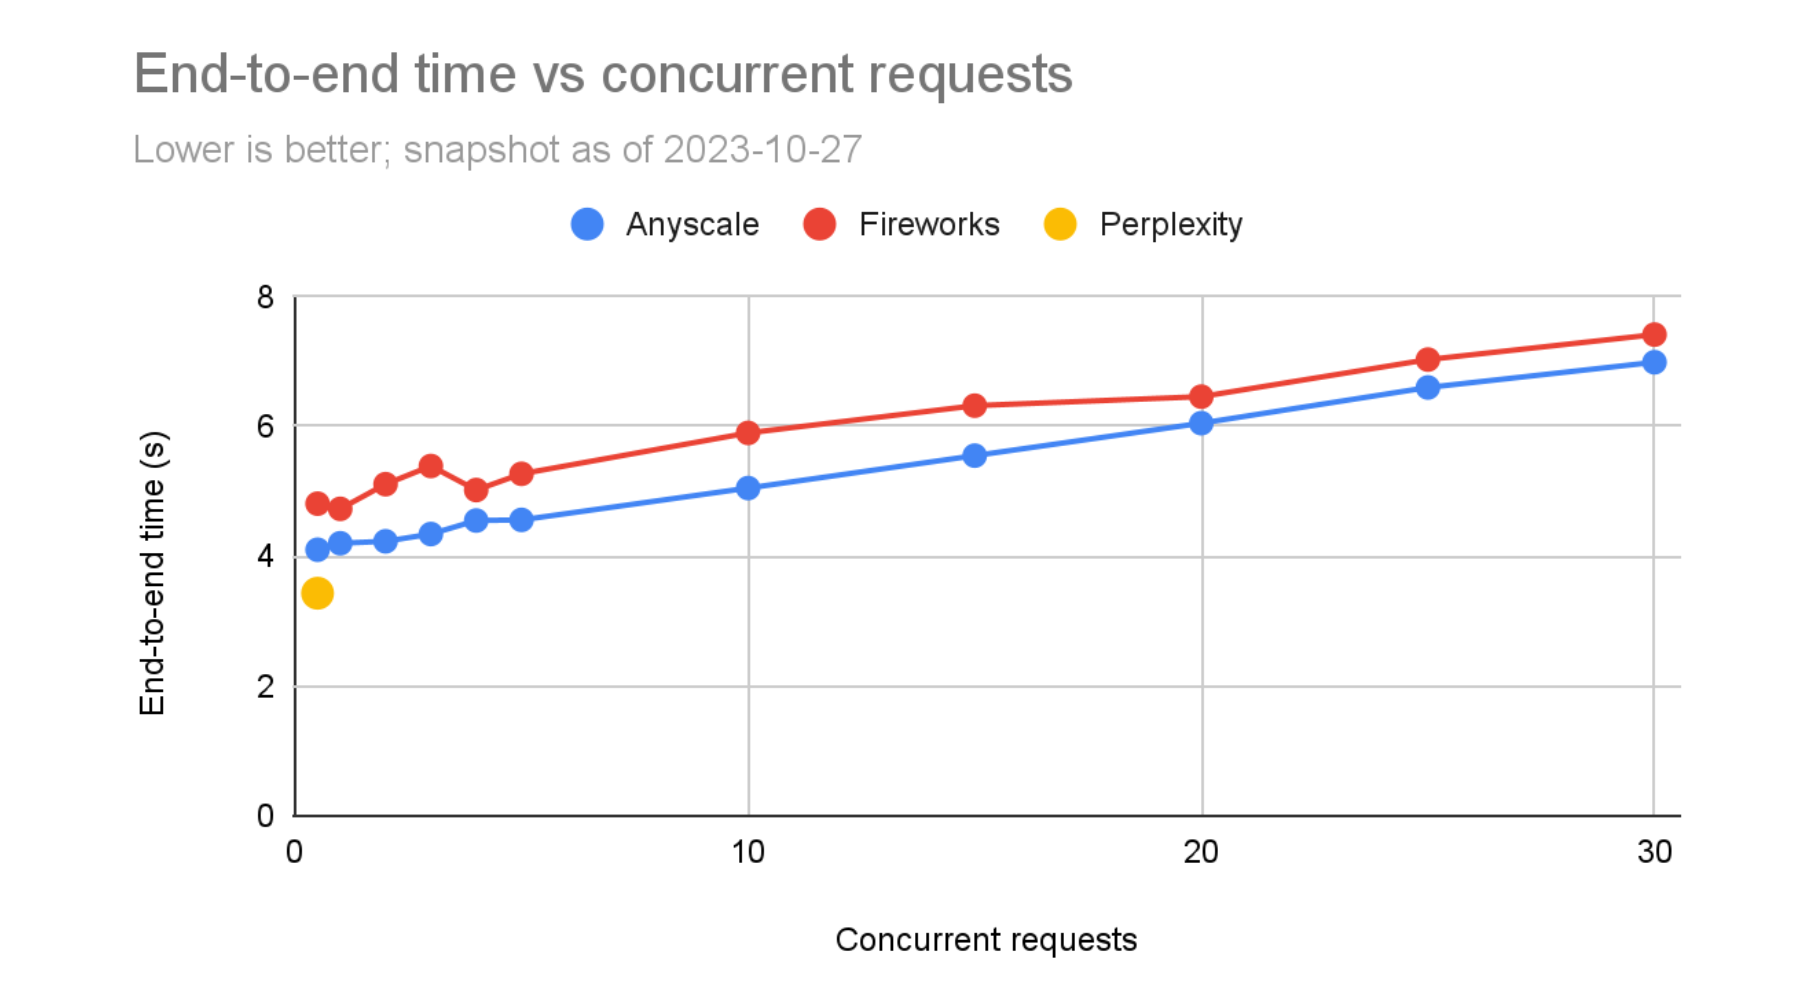
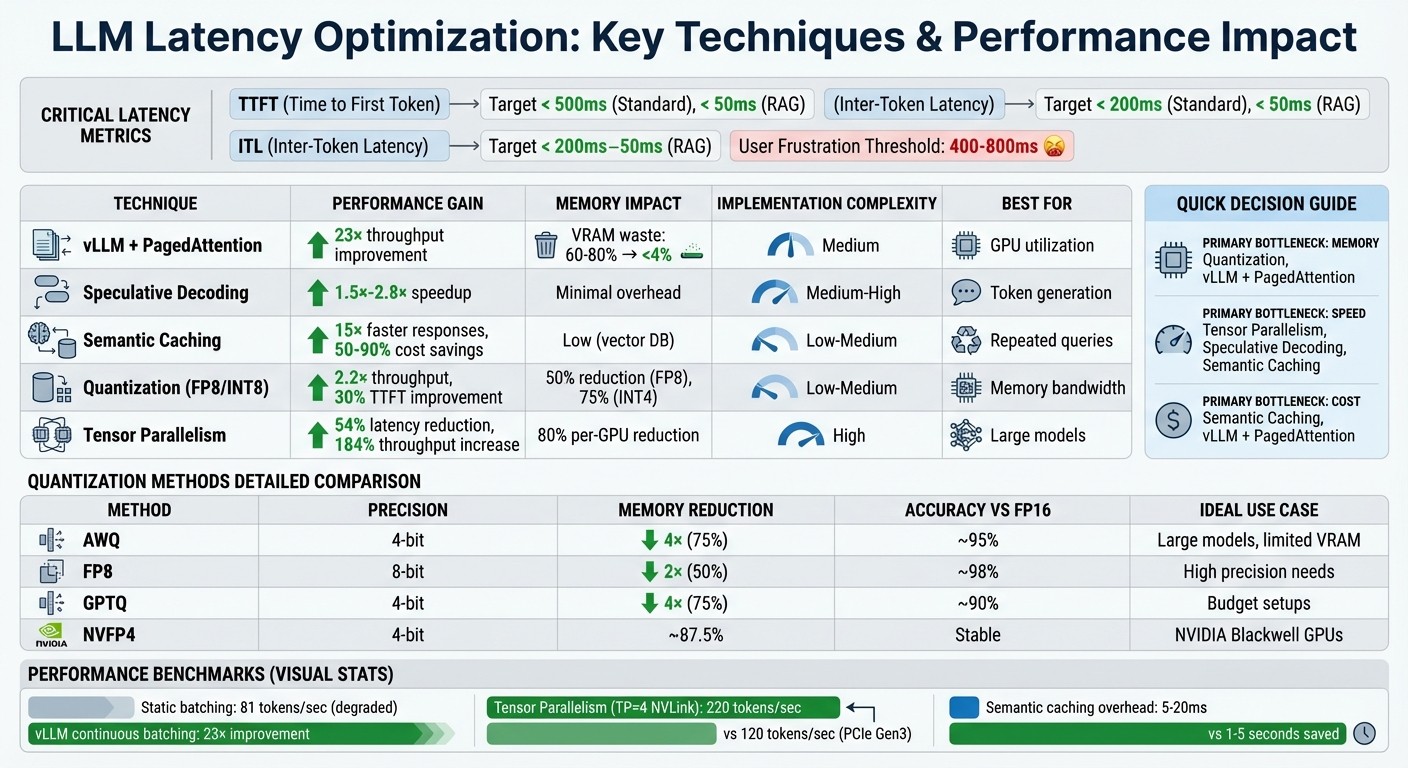
Lowest Latency AI Inference Provider for Open-Source LLMs
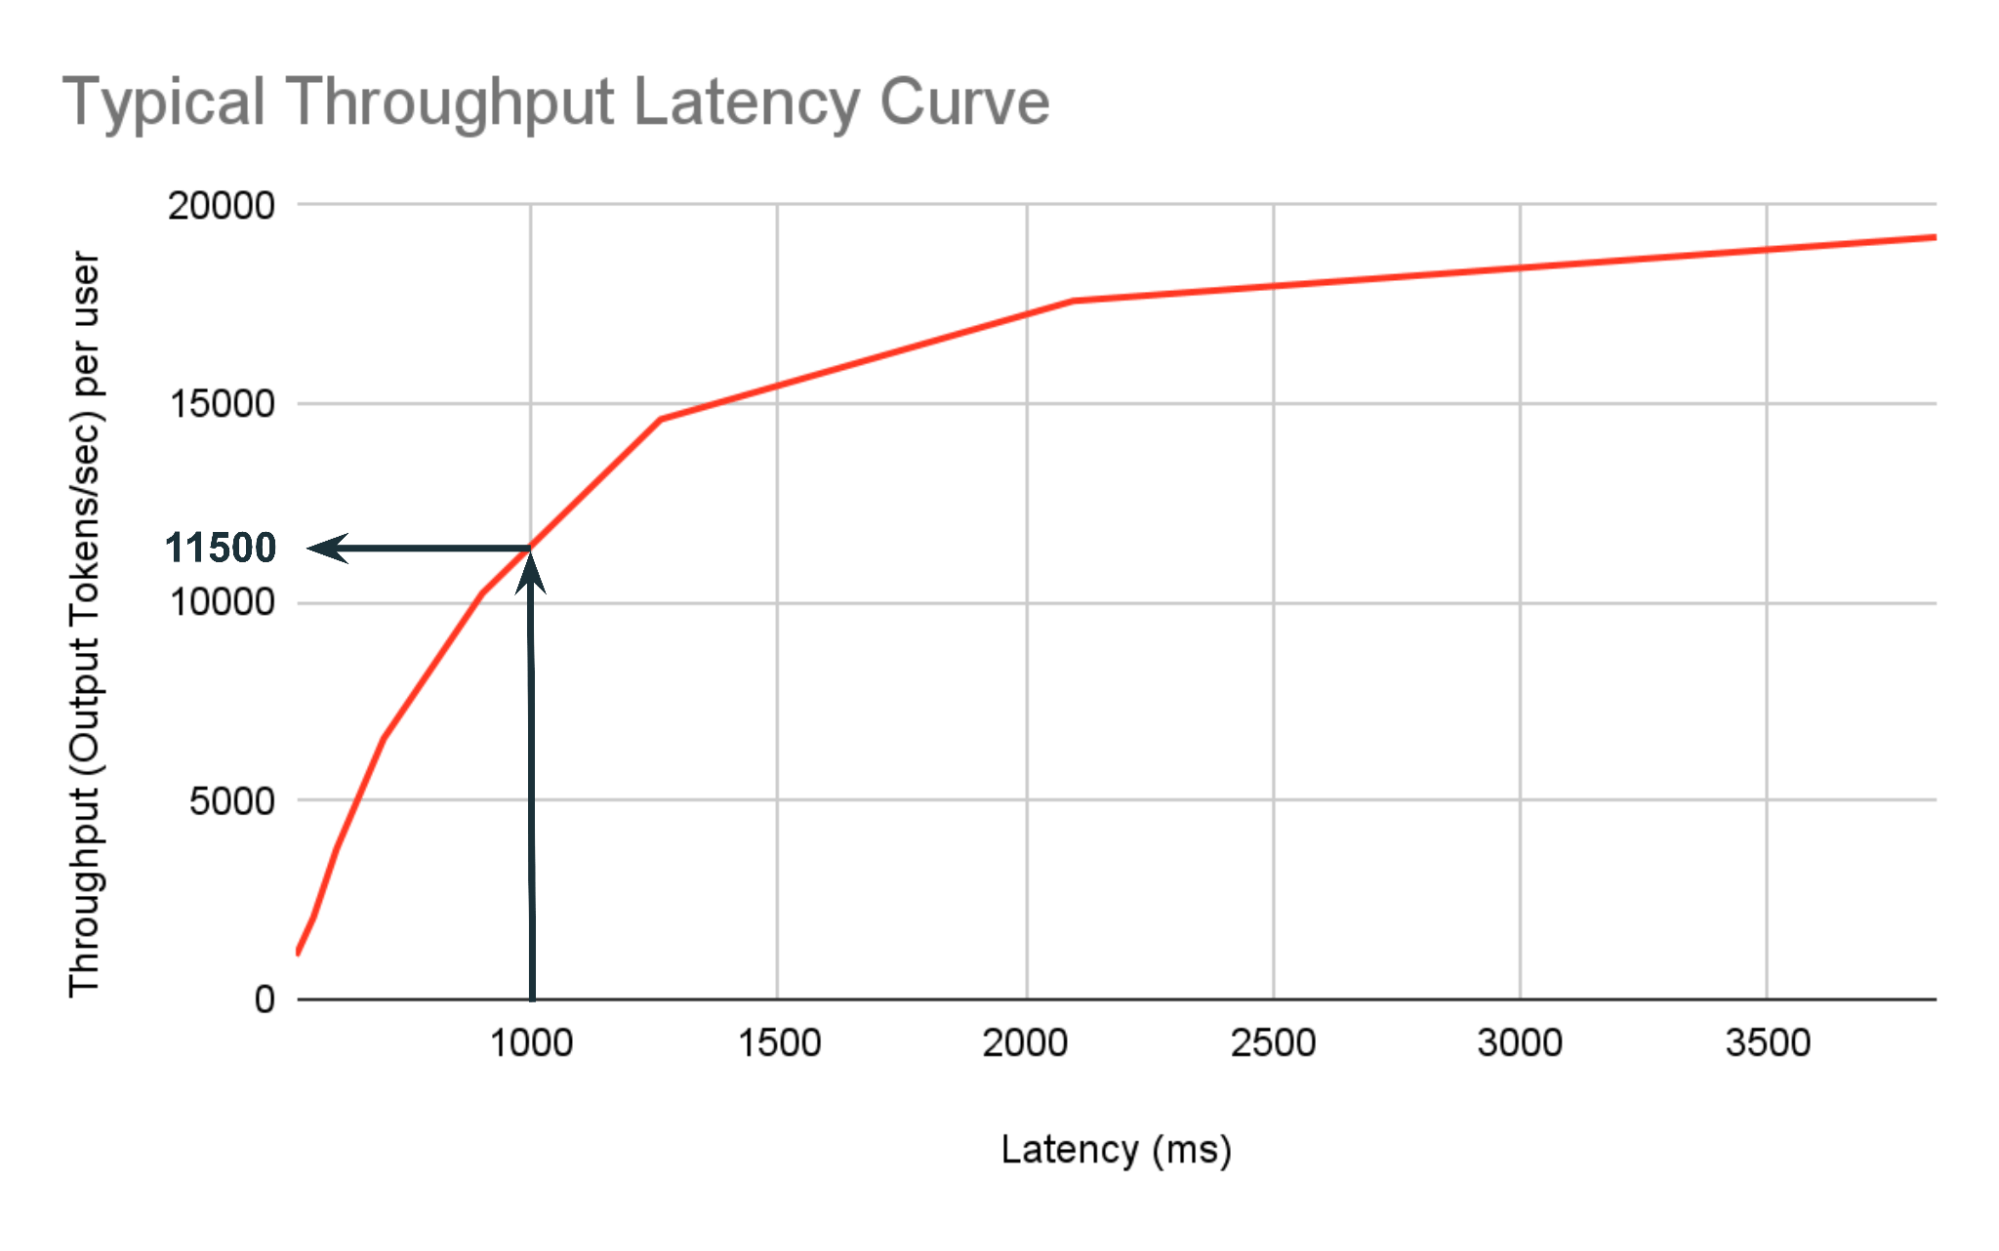
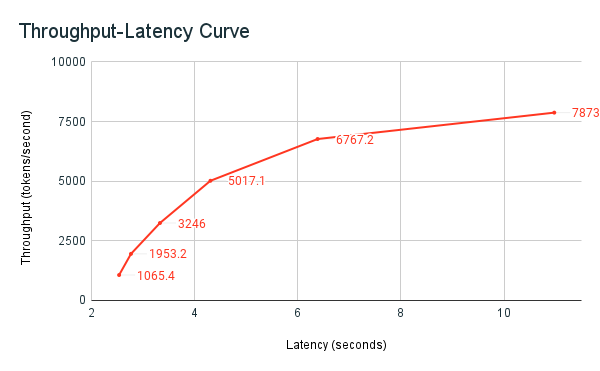
Predicted-Latency Based Scheduling for LLMs | llm-d
[论文评述] An Interpretable Latency Model for Speculative Decoding in LLM ...
Tool Use Motivation: Why LLMs Need External Tools for Accuracy ...
[論文レビュー] Leveraging Vision Capabilities of Multimodal LLMs for ...
GitHub - SvenPfiffner/PlotLLM: PlotLLM is an AI-powered Matplotlib plot ...
Flux Attention: Context-Aware Hybrid Attention for Efficient LLMs Inference
LLM Compressor: Optimize LLMs for low-latency deployments | Red Hat ...
Sustainable LLM Inference for Edge AI: Evaluating Quantized LLMs for ...
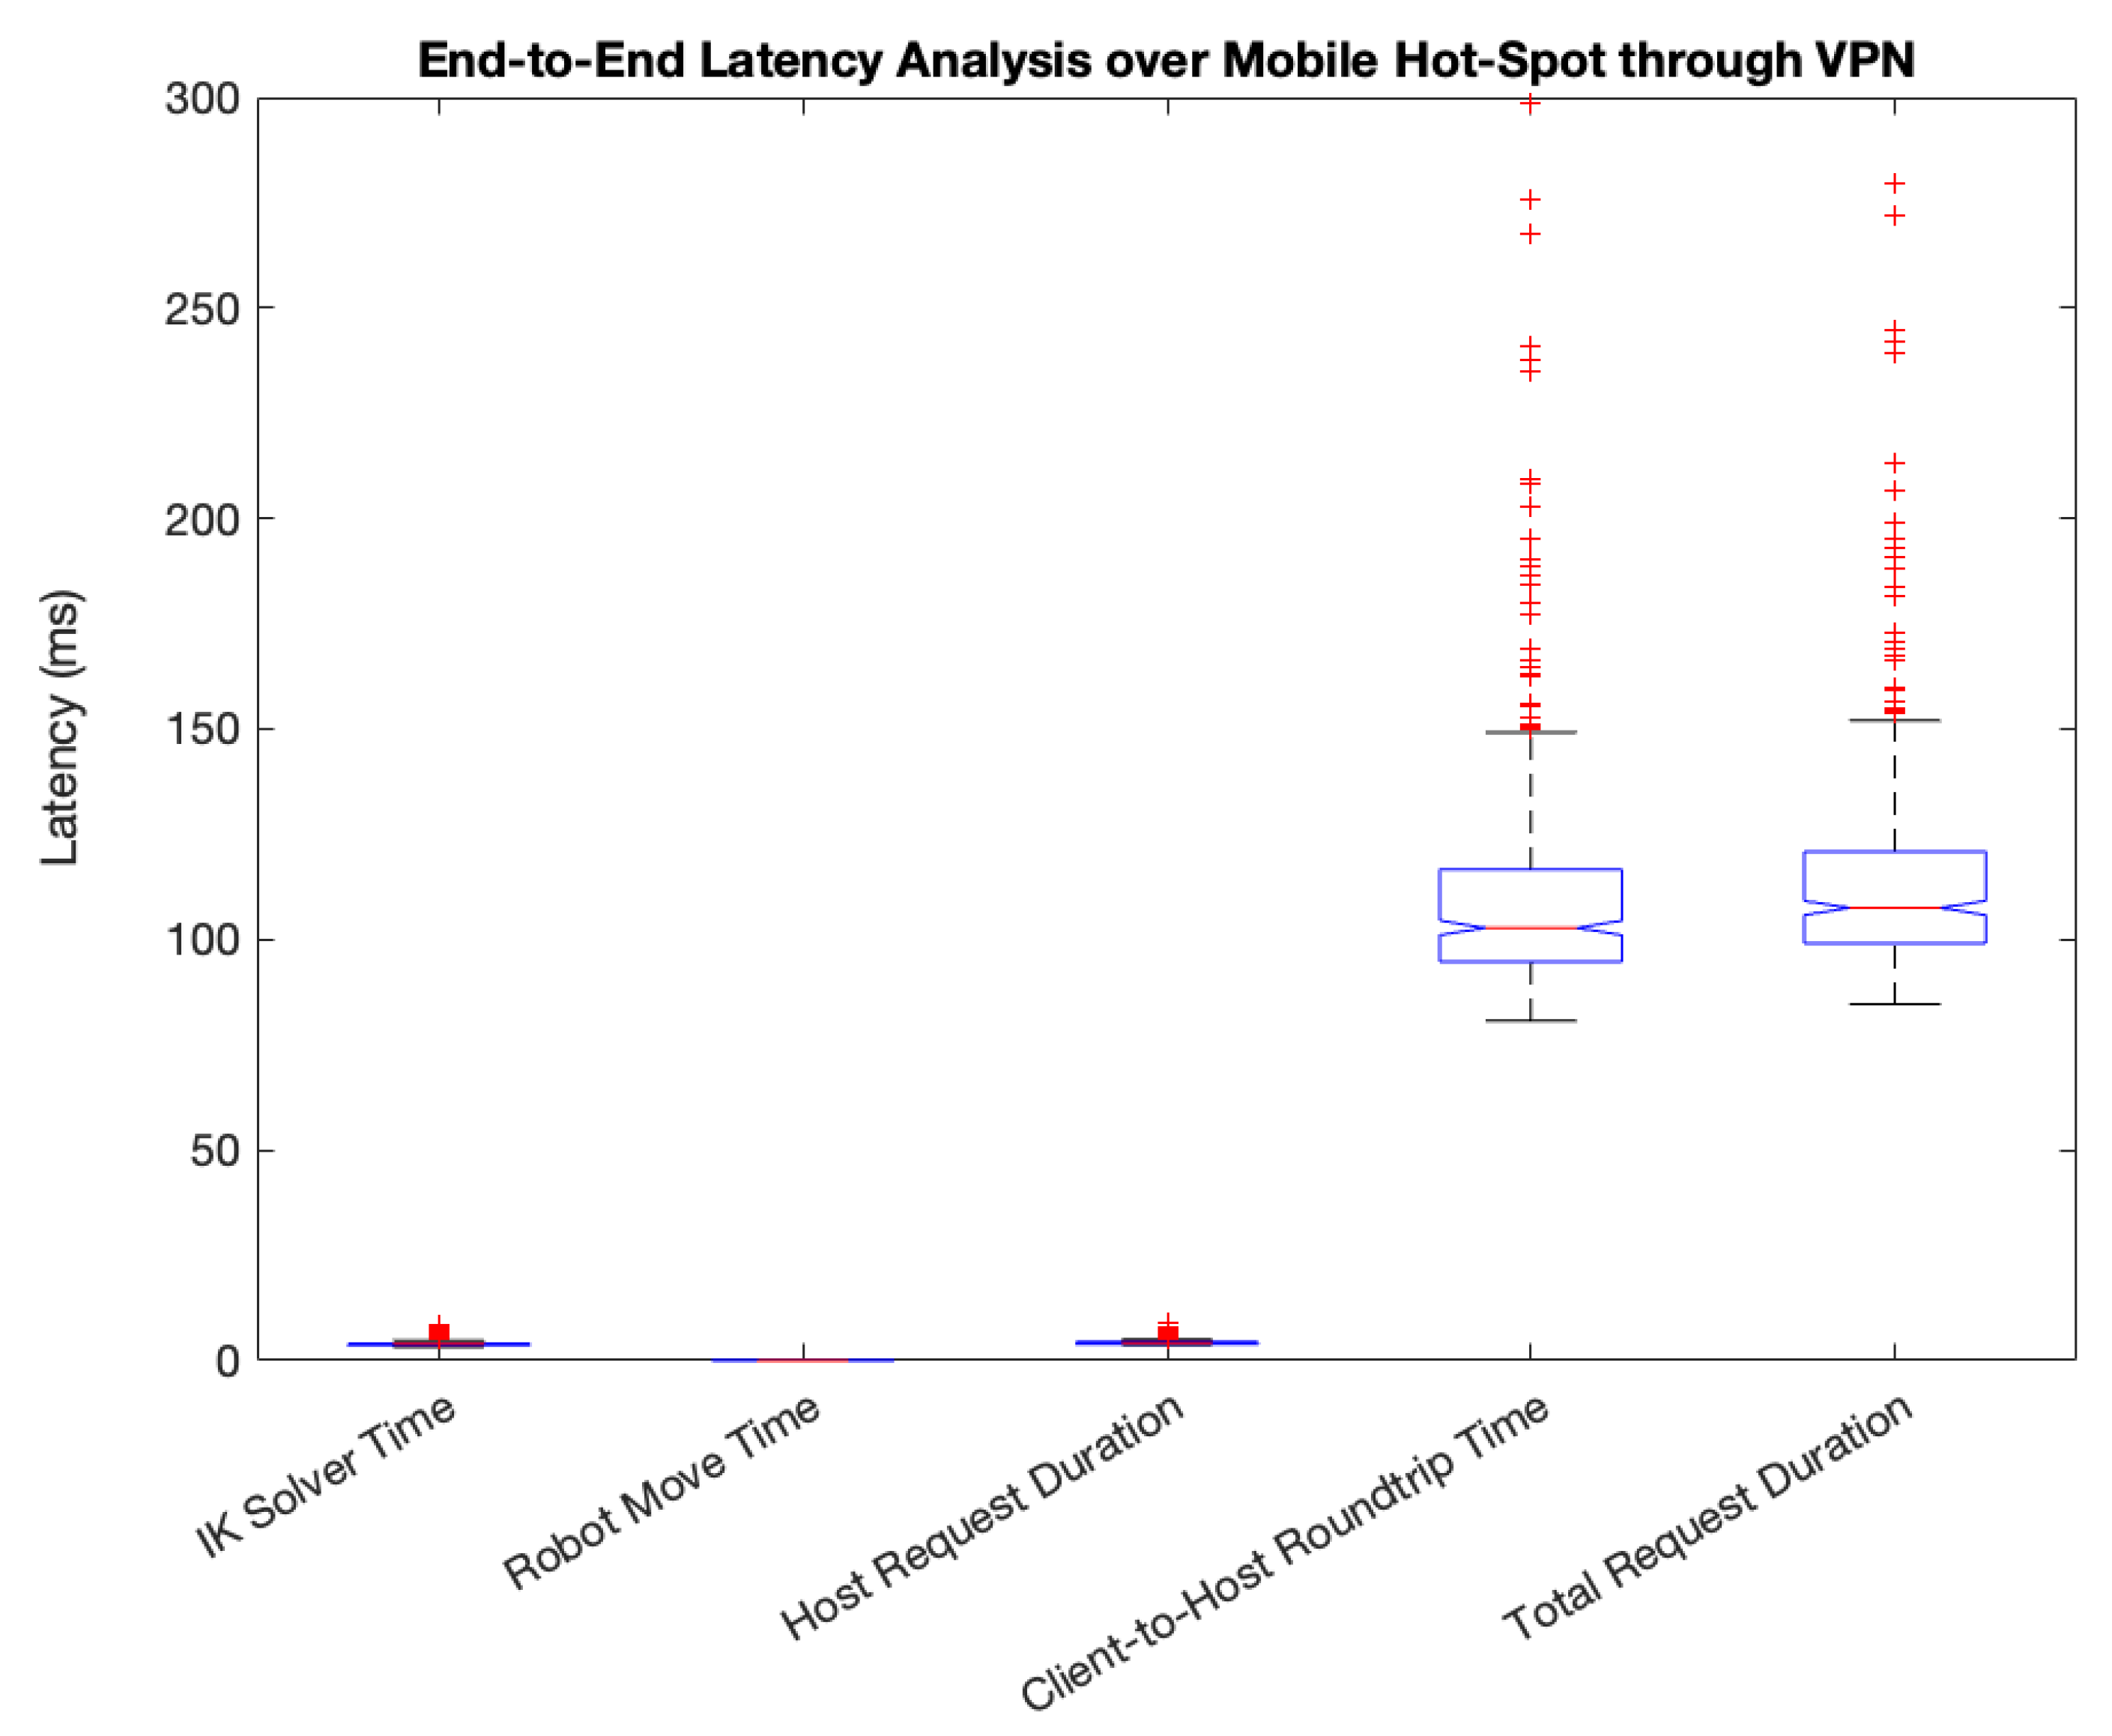
A Novel Latency Composition Analysis for Telerobotic Performance ...
PlotCraft: Pushing the Limits of LLMs for Complex and Interactive Data ...
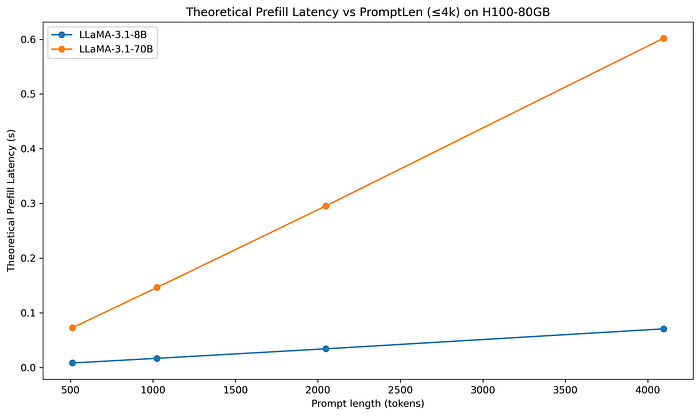
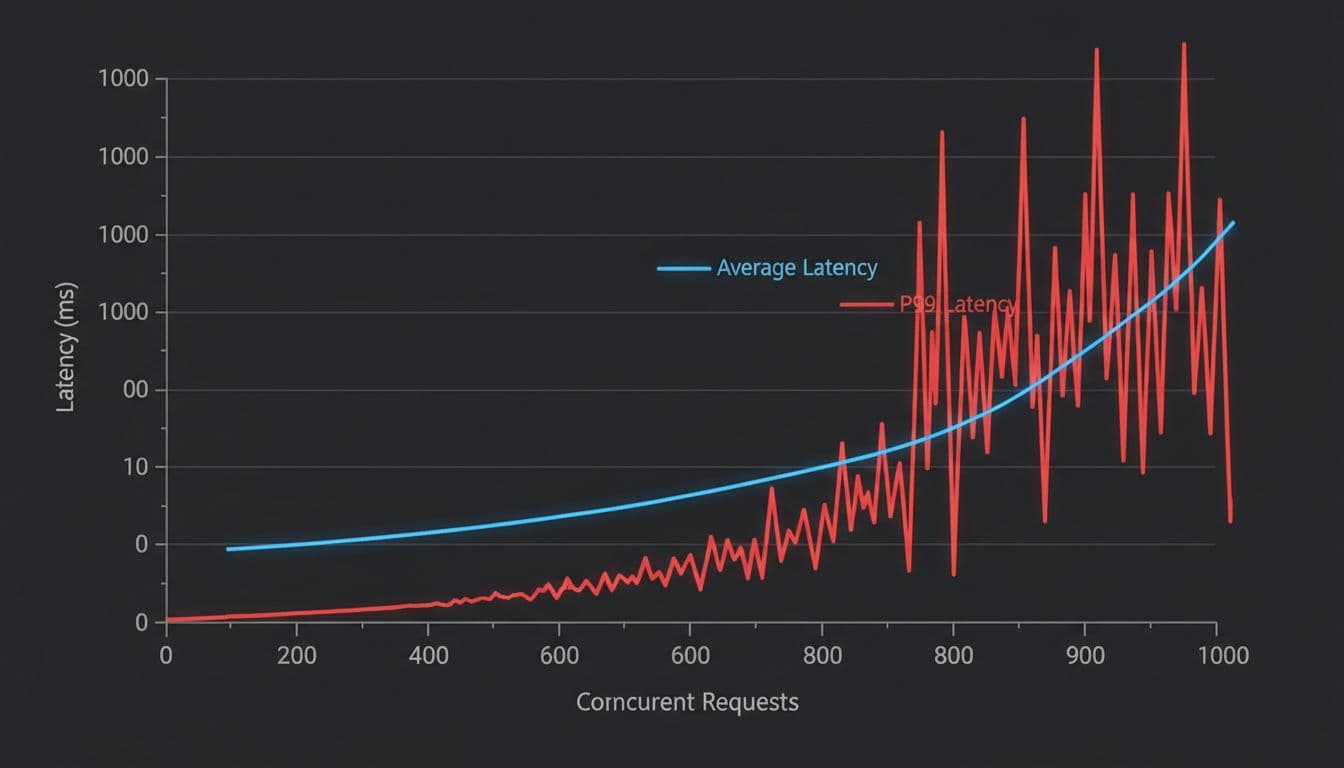
Latency profile of the LLM with the prompt. The hardware here is a ...
Flow-Controlled Scheduling for LLM Inference with Provable Stability ...
LLM Query Latency Reduced to 33ms with O(1) Computational Model ...
How to Choose the Right LLM for Your Projects: A Guide to Effective ...
Analytical Provisioning for Attention–FFN Disaggregated LLM Serving ...
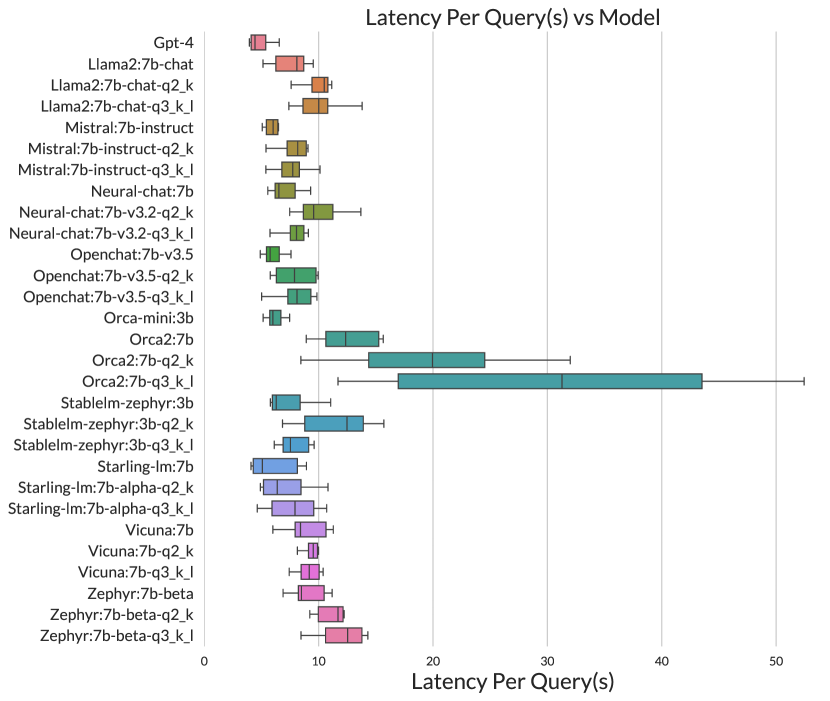
[2312.14972] A Trade-off Analysis of Replacing Proprietary LLMs with ...
Latency is the hidden enemy of MCP
Energy-Aware Scheduling for Serverless LLM Serving on Shared GPUs
The Impact of Response Latency and Task Type on Human-LLM Interaction ...
Data center design requirements for AI workloads. A Comprenshive guide.
LLM4FaaS: No-Code Application Development using LLMs and FaaS ...
LLM Latency Benchmark Report
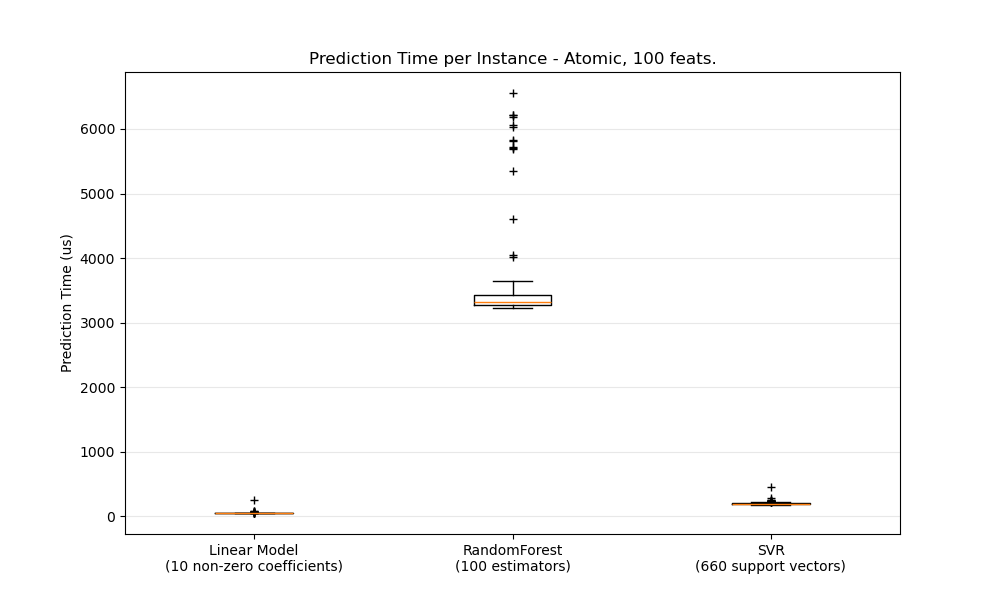
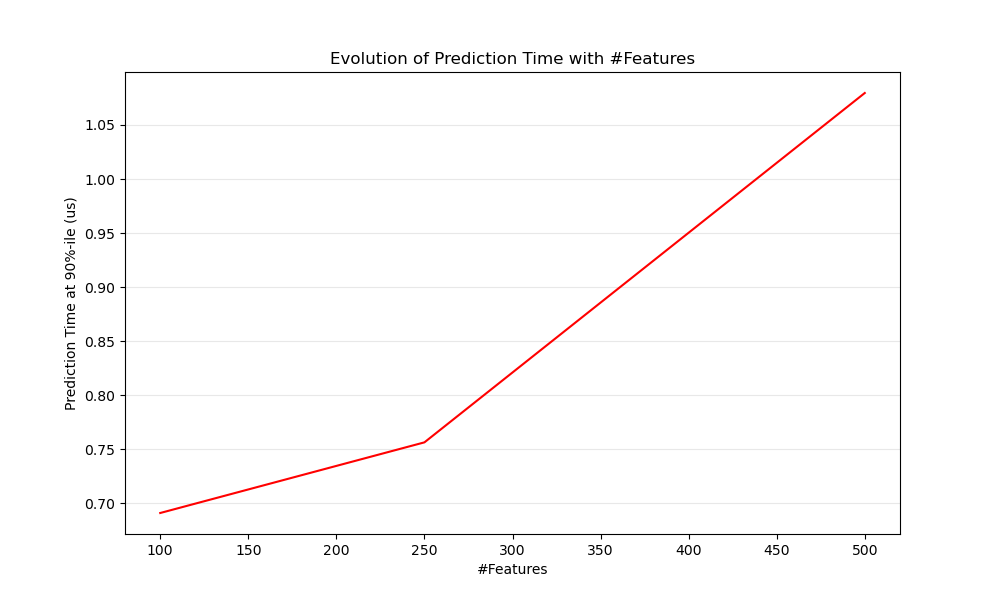
Prediction Latency — scikit-learn 1.9.0 documentation - sklearn
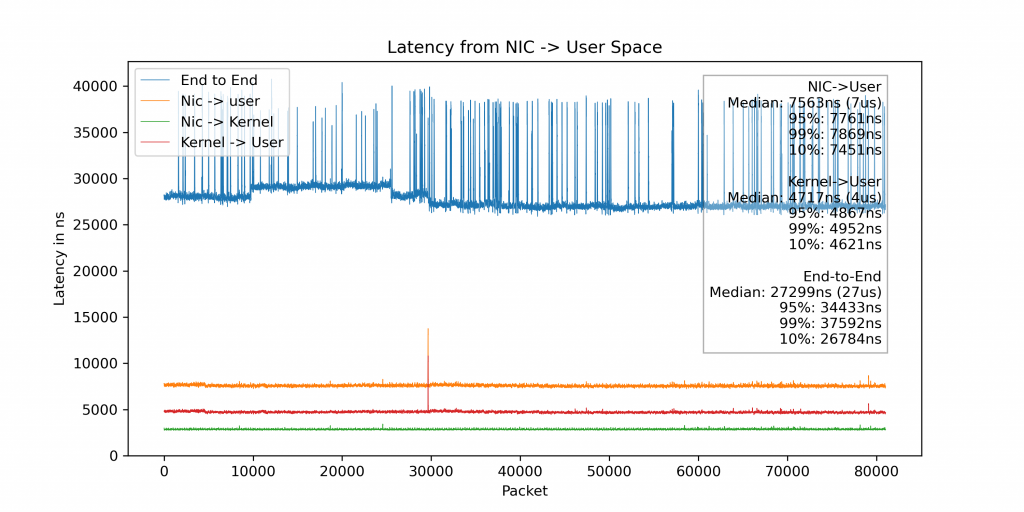
How to measure network latency using hardware timestamps | IIJ ...
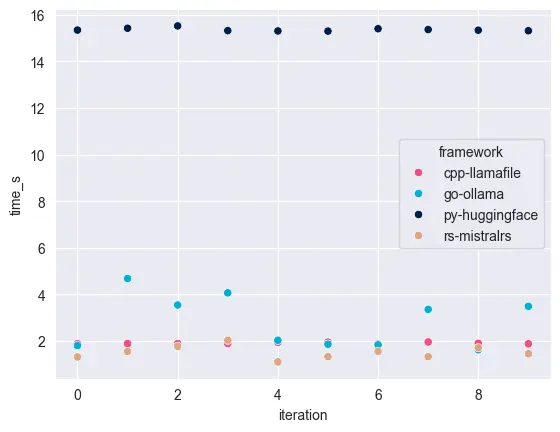
Consumer LLMs Face-Off: Real Performance Data You Need to See - Ask Alice
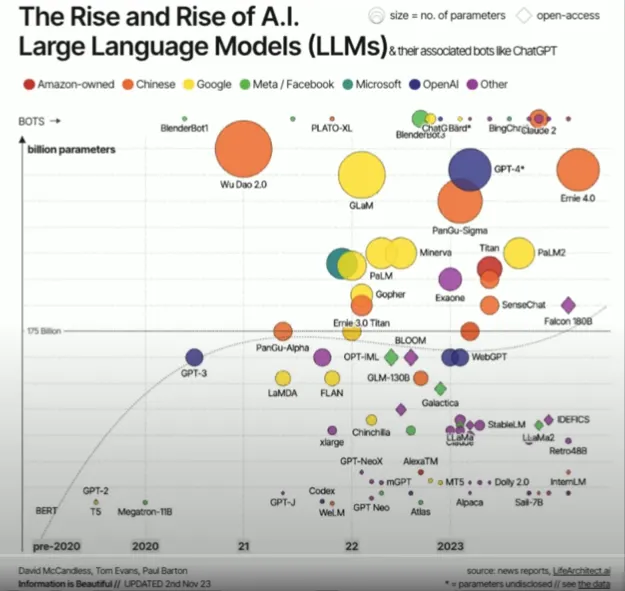
How LLMs are Changing Computing - by Antonio Linares
Ilyas Moutawwakil on Twitter: "🔥One plot to compare them ALL🏆 If you're ...
LLM serving latency benchmark
Scaling Laws for LLMs: From GPT-3 to o3
Latency SLOs Done Right | PPTX
Prediction Latency — scikit-learn 1.5.2 documentation
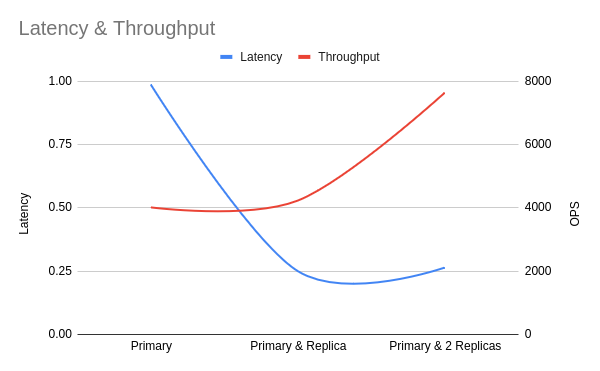
How SageMaker Enhances Salesforce Einstein’s LLM Latency and Throughput
️Context Length Killed the Latency Star 🌟 If you are building latency ...
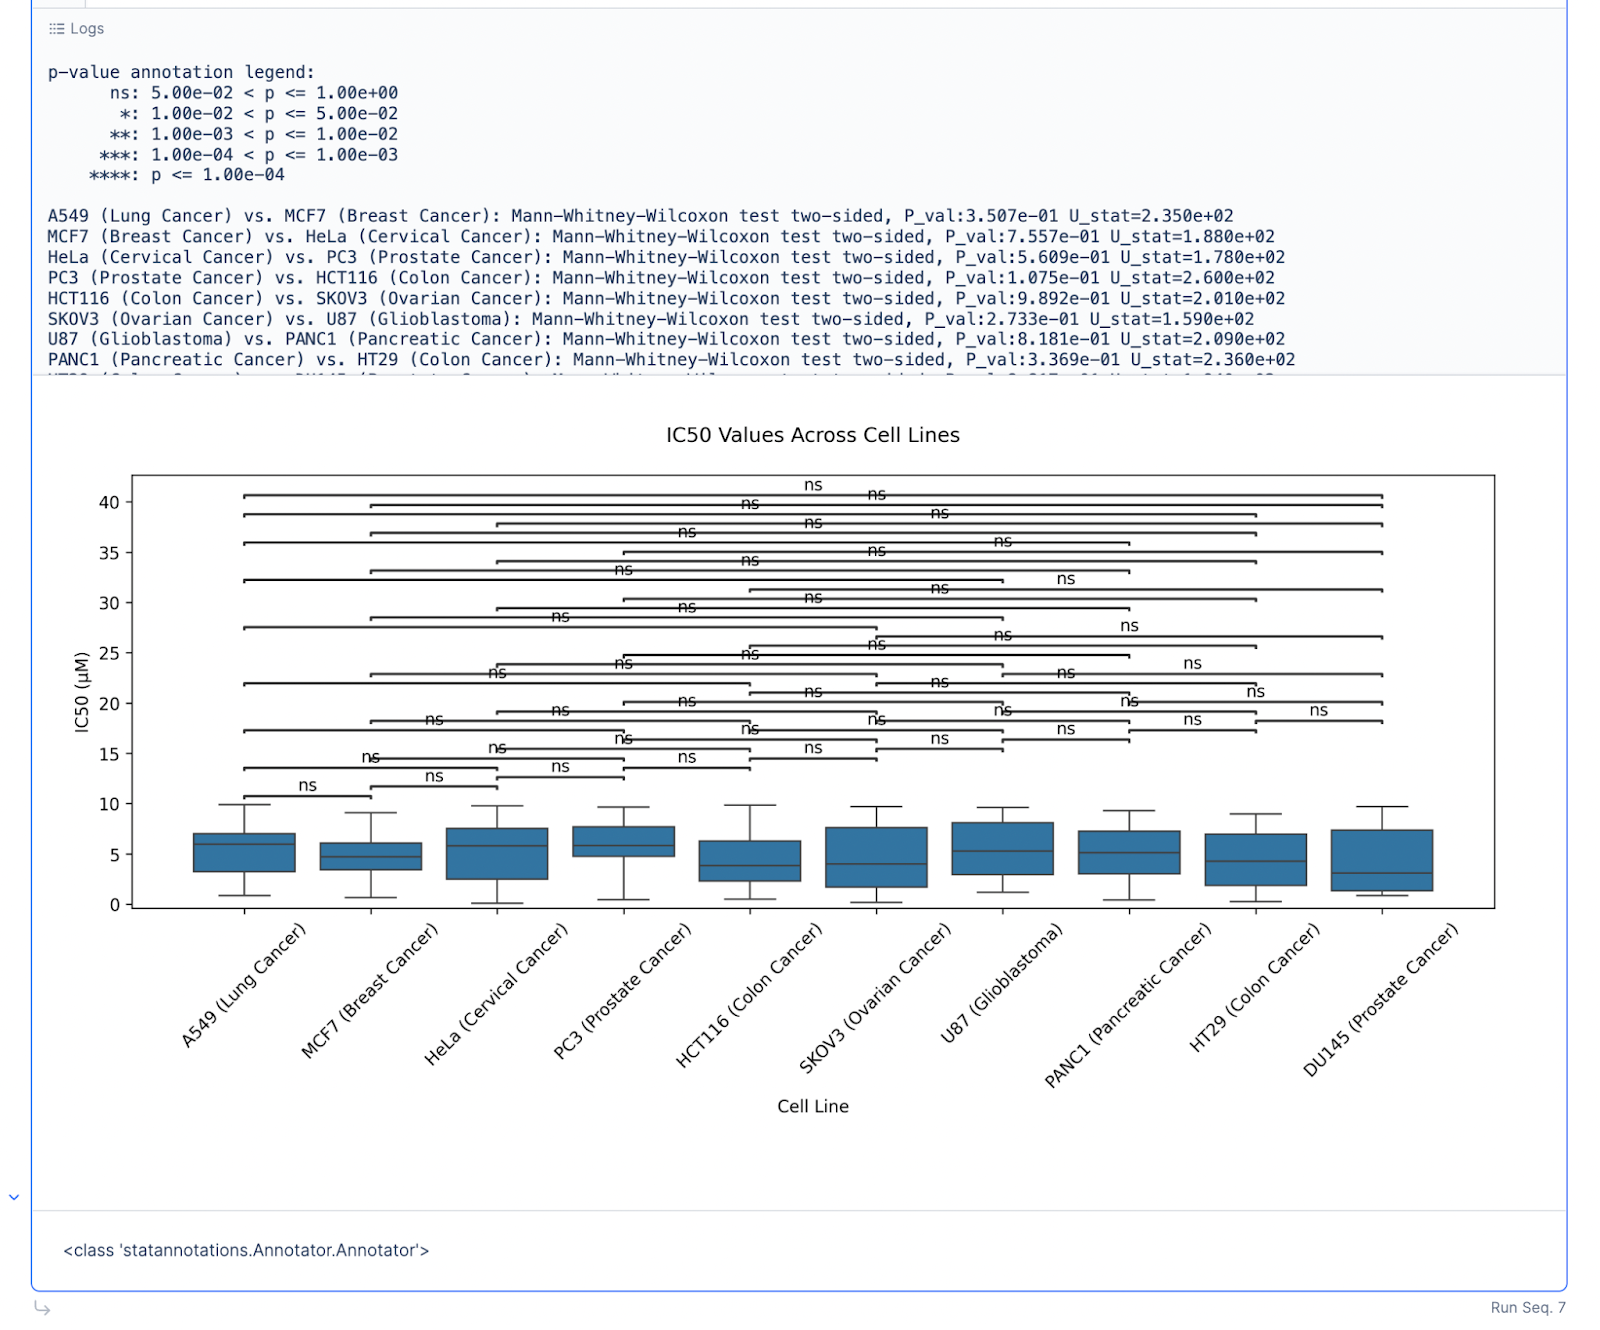
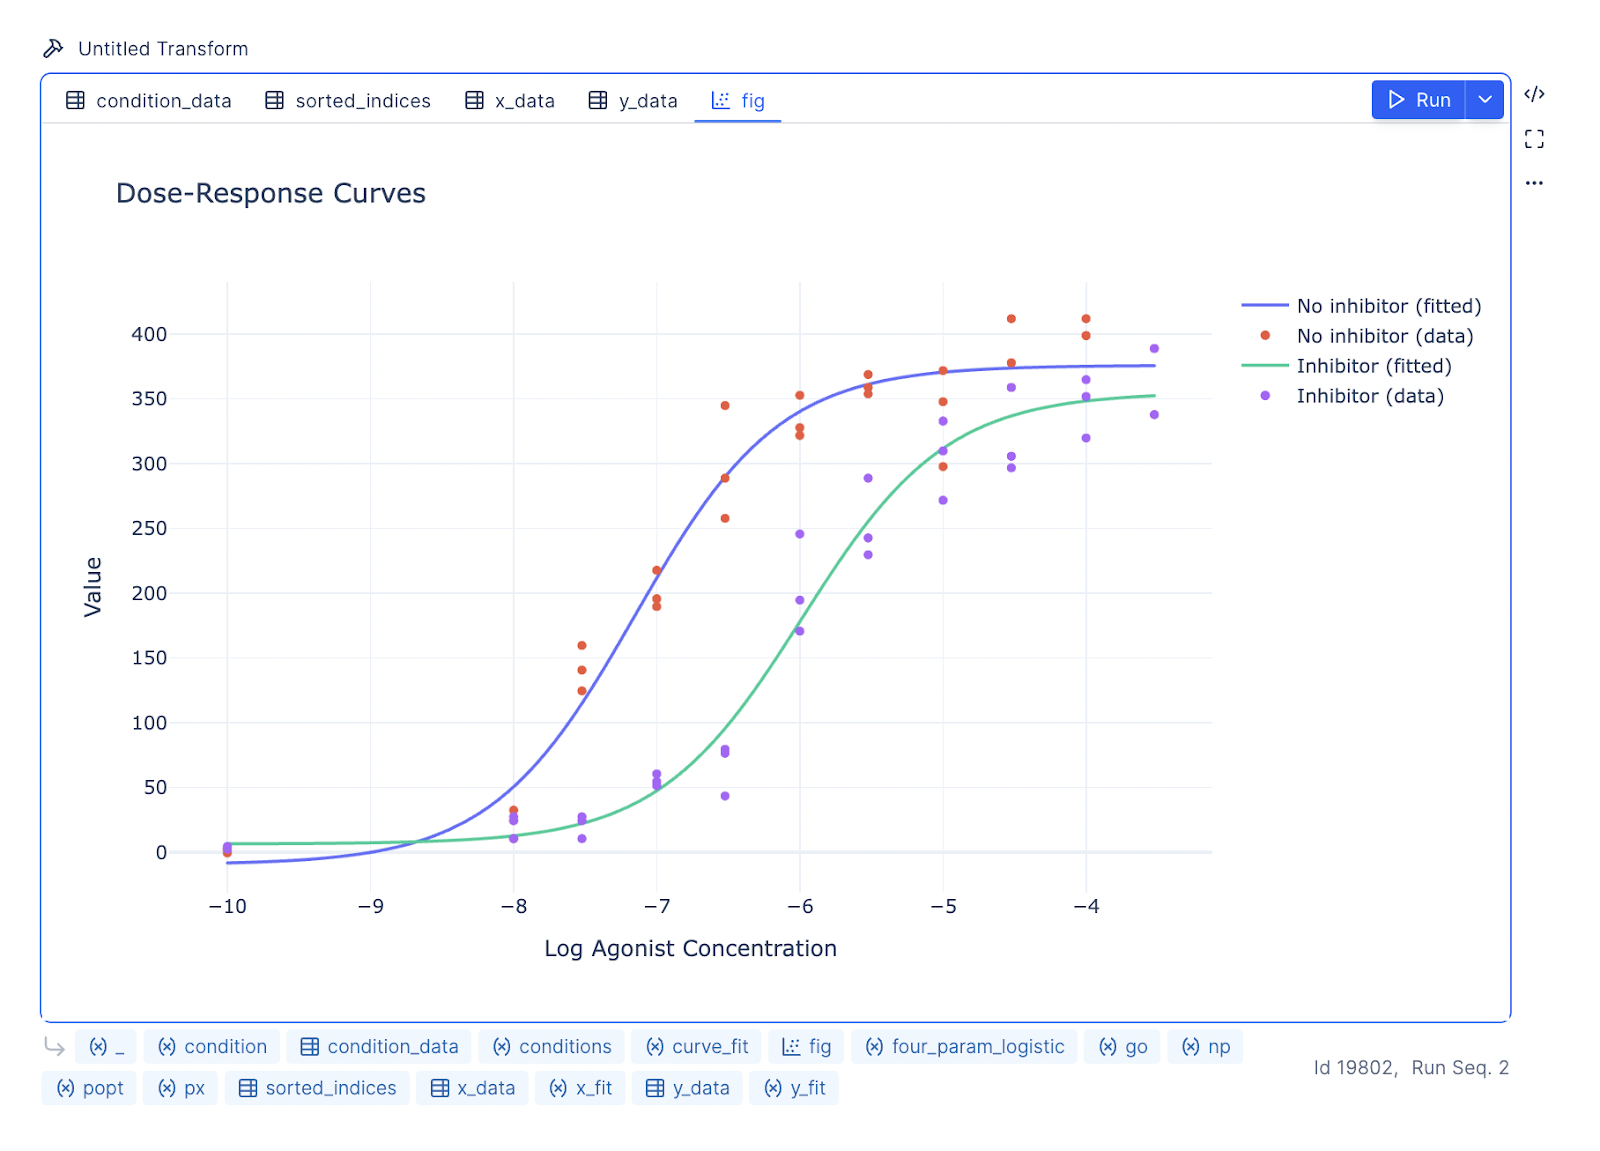
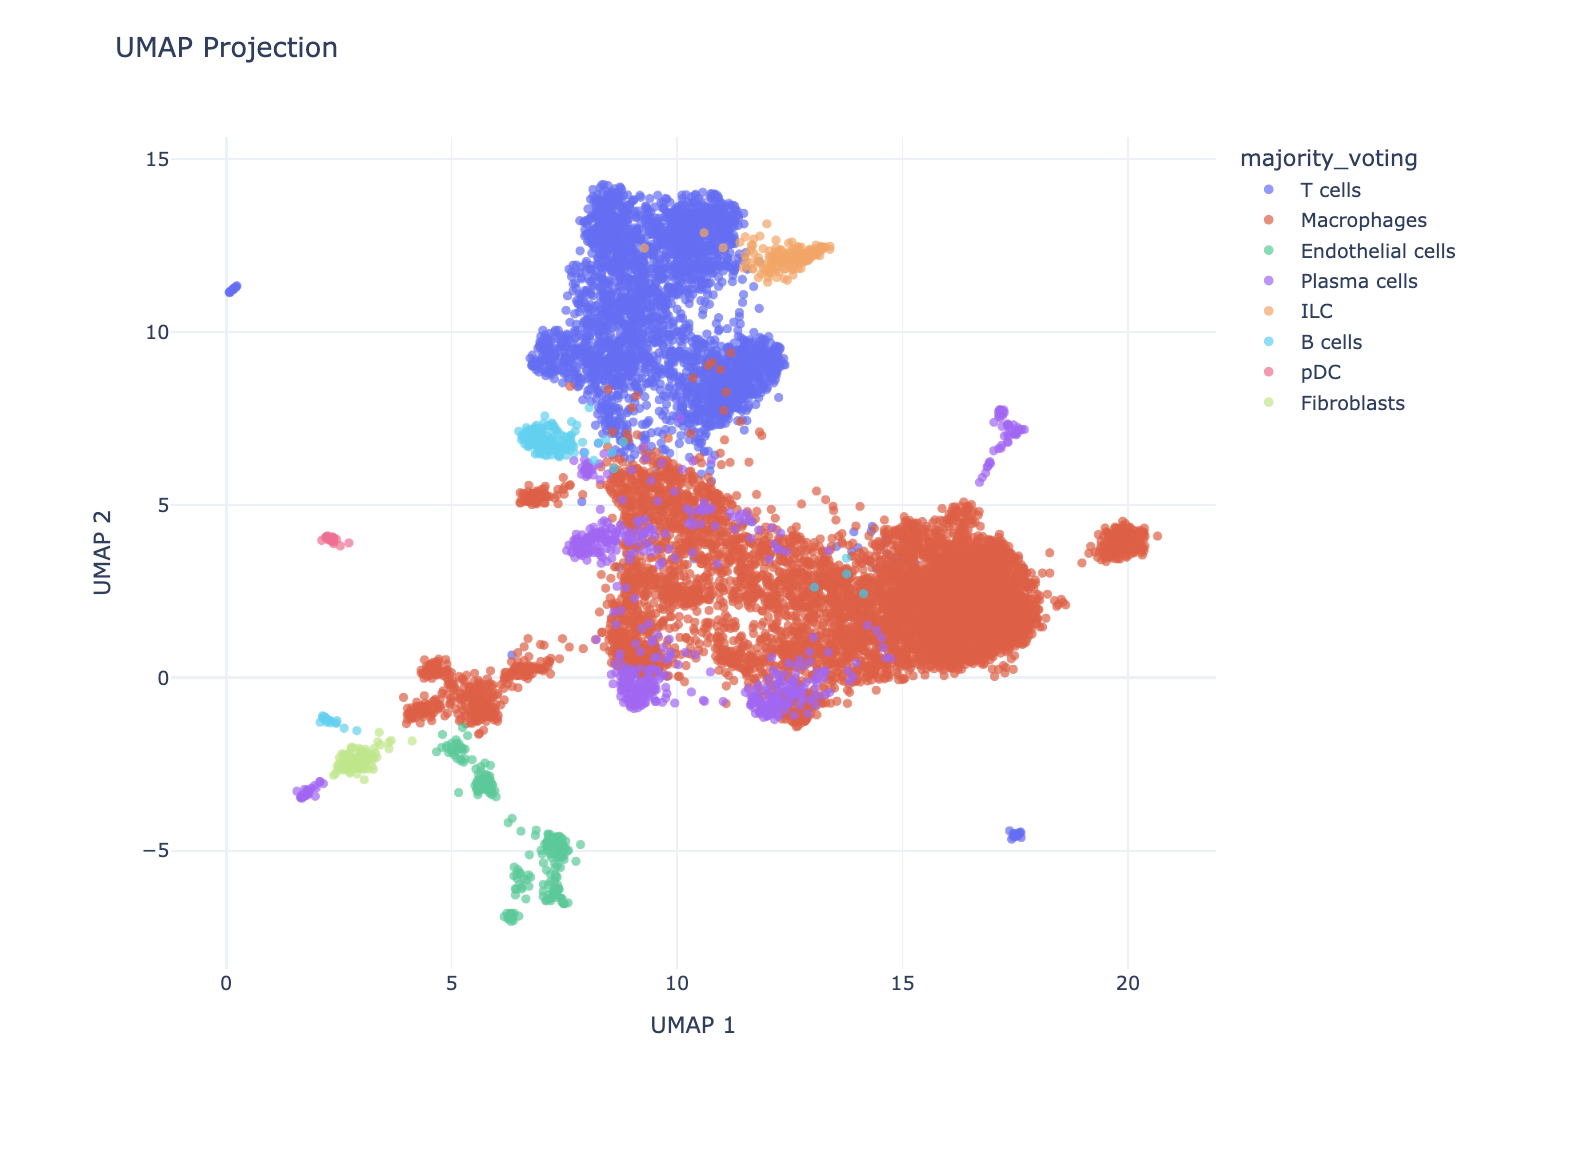
LLM Integration for Plots - LatchBio
Prediction Latency — scikit-learn 0.17.dev0 documentation
A Policy-Aware Edge LLM-RAG Framework for Internet of Battlefield ...
MobileLLM-Flash: Latency-Guided On-Device LLM Design for Industry Scale ...
Reproducible Performance Metrics for LLM inference
[2505.19634] Faster and Better LLMs via Latency-Aware Test-Time Scaling
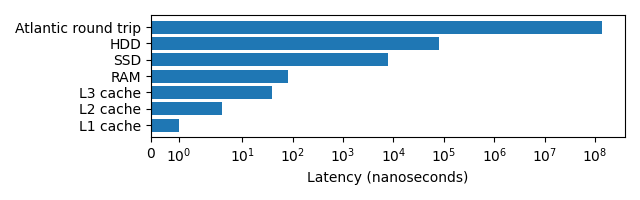
Performance Profiling & Optimisation (Python): Understanding Latency
ProactiveLLM: Learning Active Interaction for Streaming Large Language ...
Latency - Q&A - SigmaDSP Processors & SigmaStudio Dev. Tool - EngineerZone
Context Rot: Why LLMs Are Getting Dumber? - by Nilesh Barla
[2506.09061] EdgeProfiler: A Fast Profiling Framework for Lightweight ...
🧠 Day 5: Most Used LLMs in 2025 — Who’s Leading the AI Revolution? | by ...
Real-Time LLMs: Optimizing Latency in Streaming | Latitude
SafeConstellations: Mitigating Over-Refusals in LLMs Through Task-Aware ...
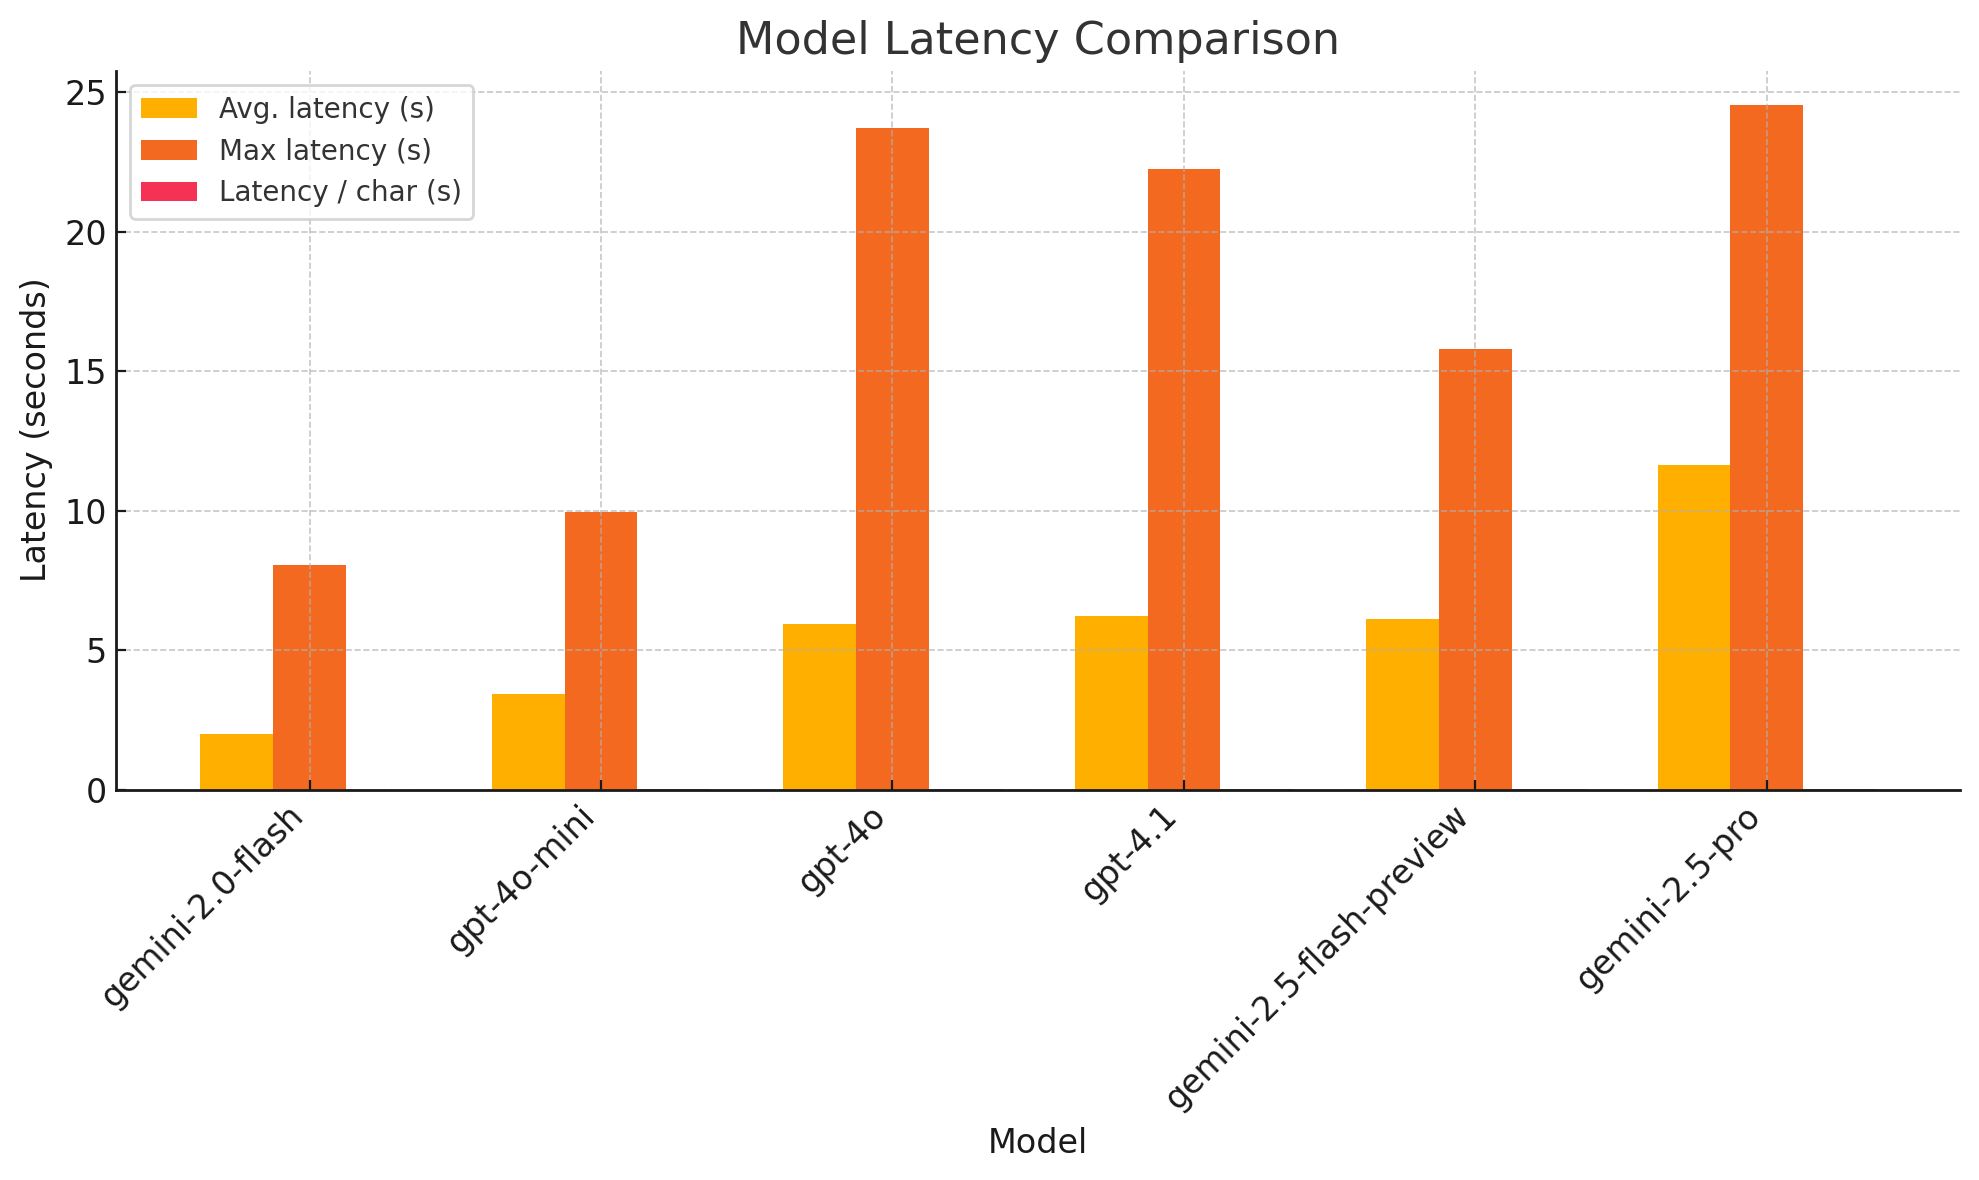
LLM API Latency Compared: Speed Benchmarks 2026 — APIpulse
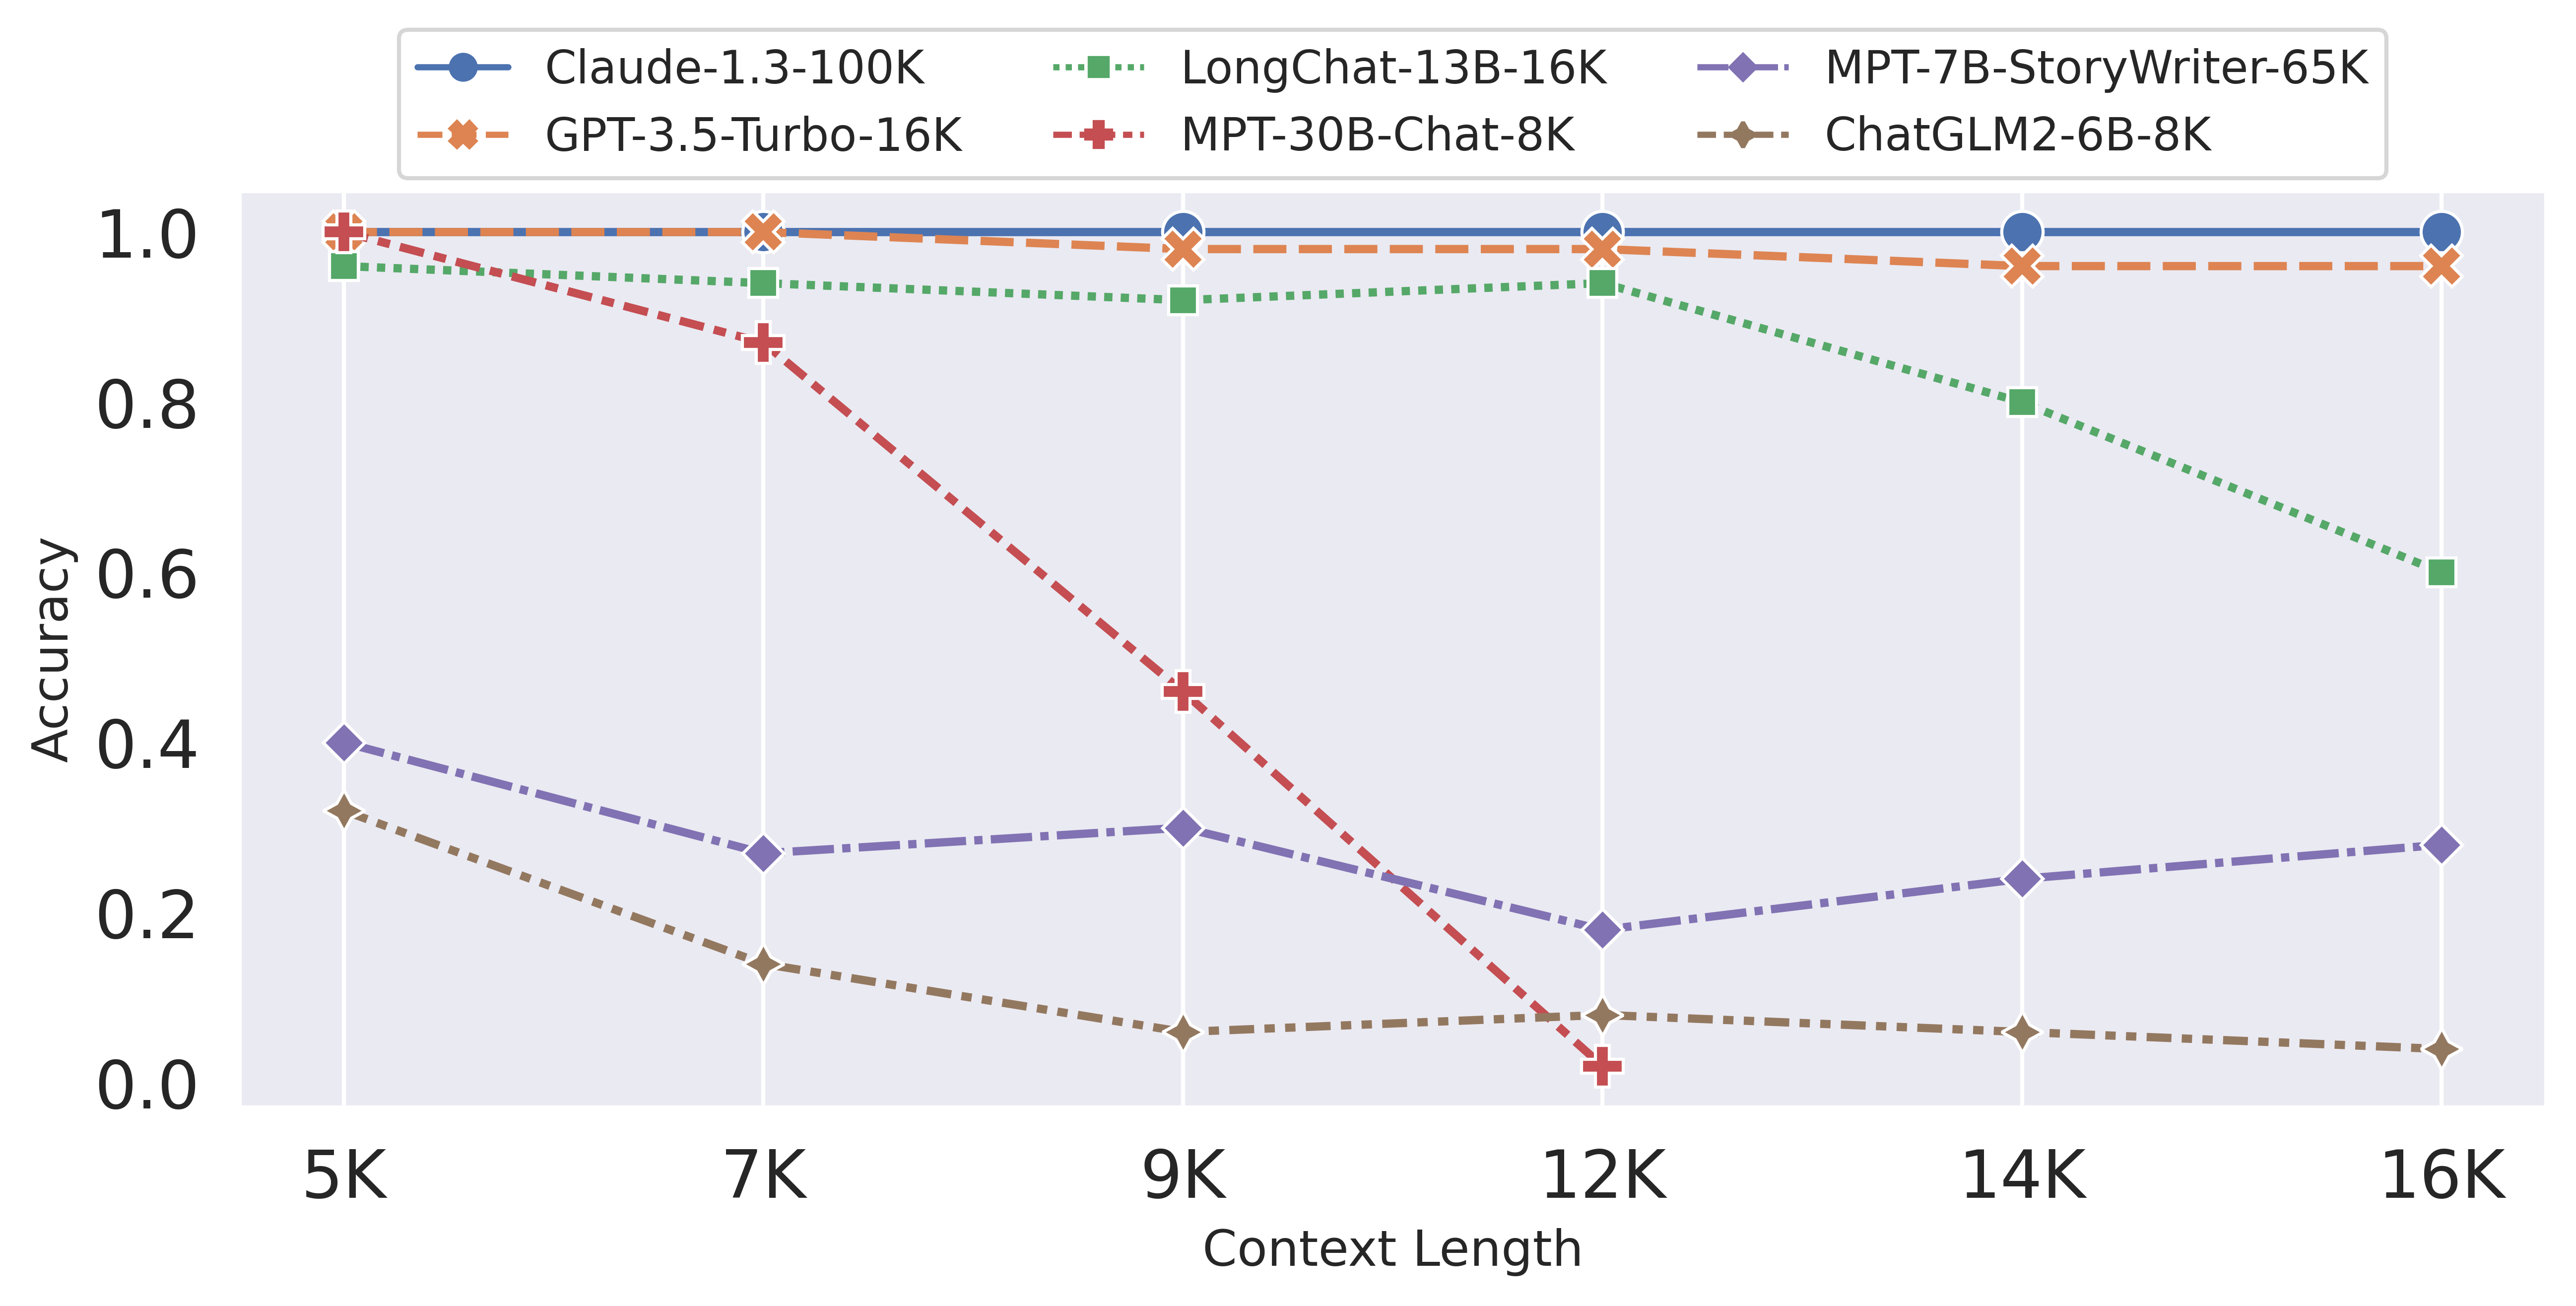
How Long Can Open-Source LLMs Truly Promise on Context Length? | LMSYS Org
Exploring the benefits of Large Language Models for Recommendation ...
Teaching Code LLMs to Use Autocompletion Tools in Repository-Level Code ...
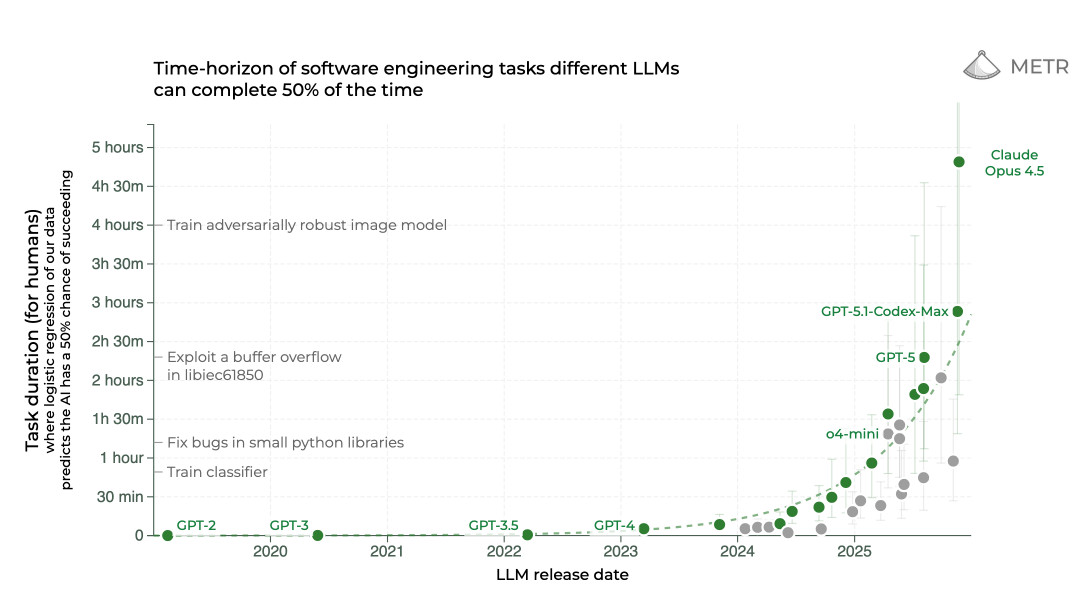
2025: The year in LLMs
LoopLLM: Transferable Energy-Latency Attacks in LLMs via Repetitive ...
Customizing Matplotlib with style sheets and rcParams — Matplotlib 3.7. ...
How do response time and latency factor into LLM evaluation?
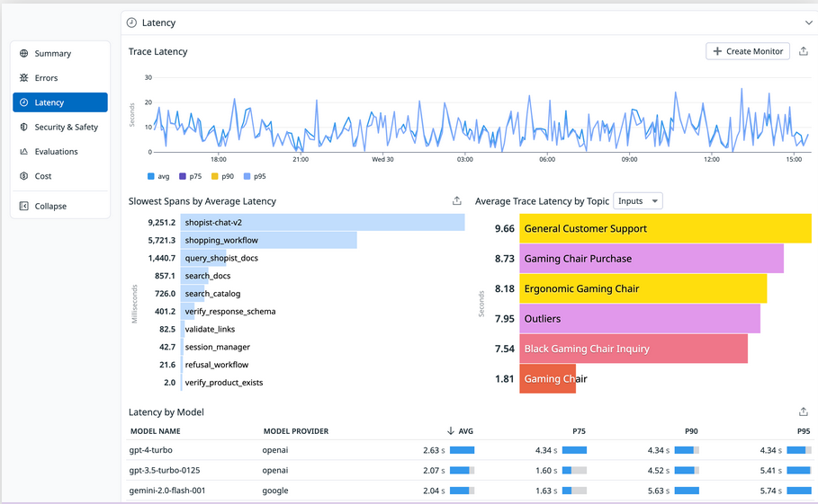
Monitoring LLM Systems: Metrics, Logging, Alerting, and Dashboards ...
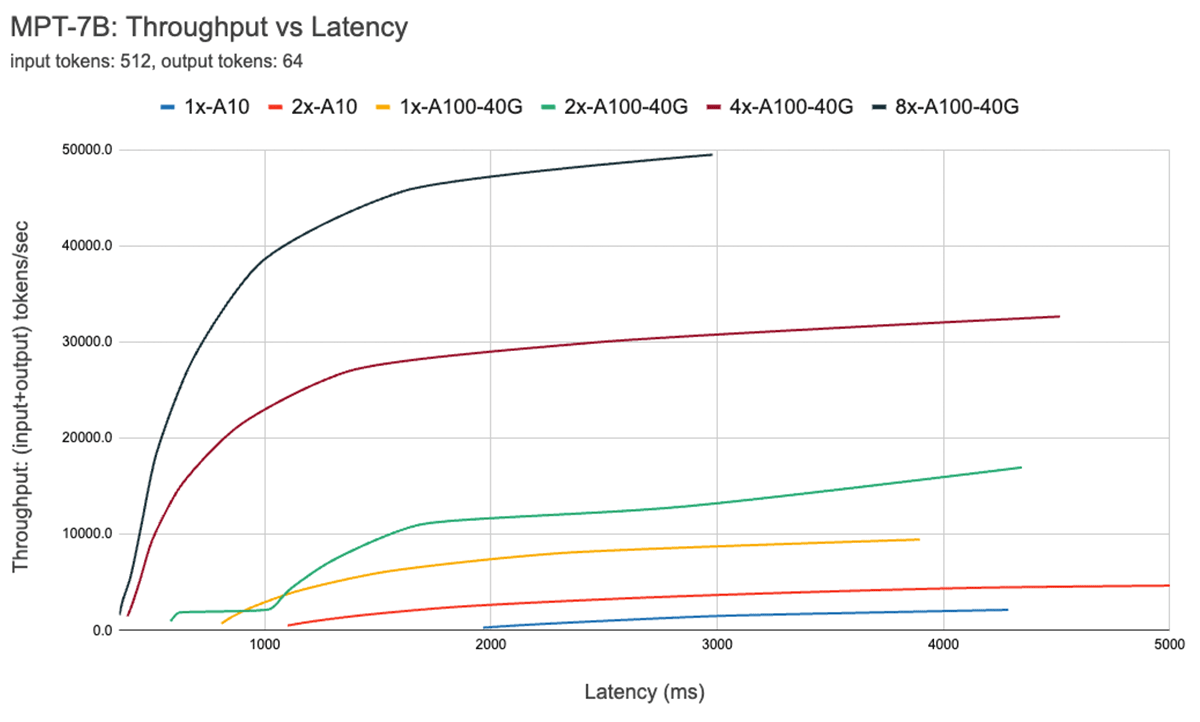
LLM Inference Performance Engineering: Best Practices | Databricks Blog
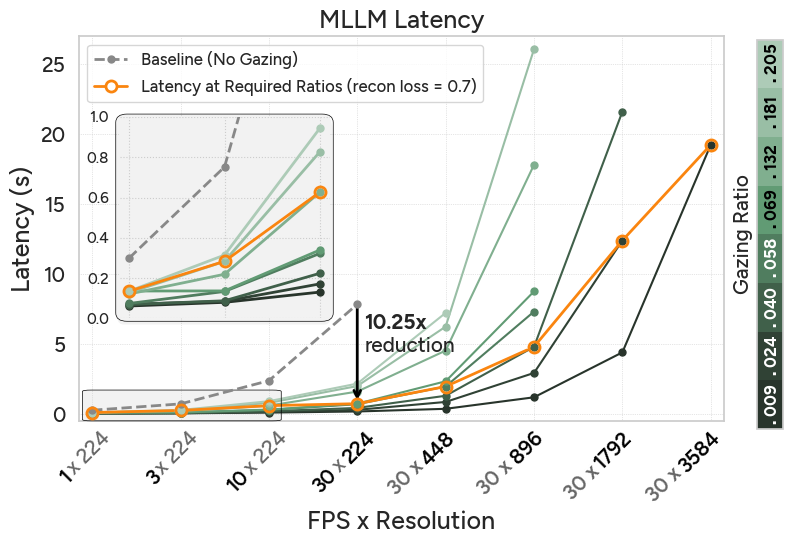
AutoGaze
LLM Inference Benchmarking Guide: NVIDIA GenAI-Perf and NIM | NVIDIA ...
LLM Inference - EcoLogits
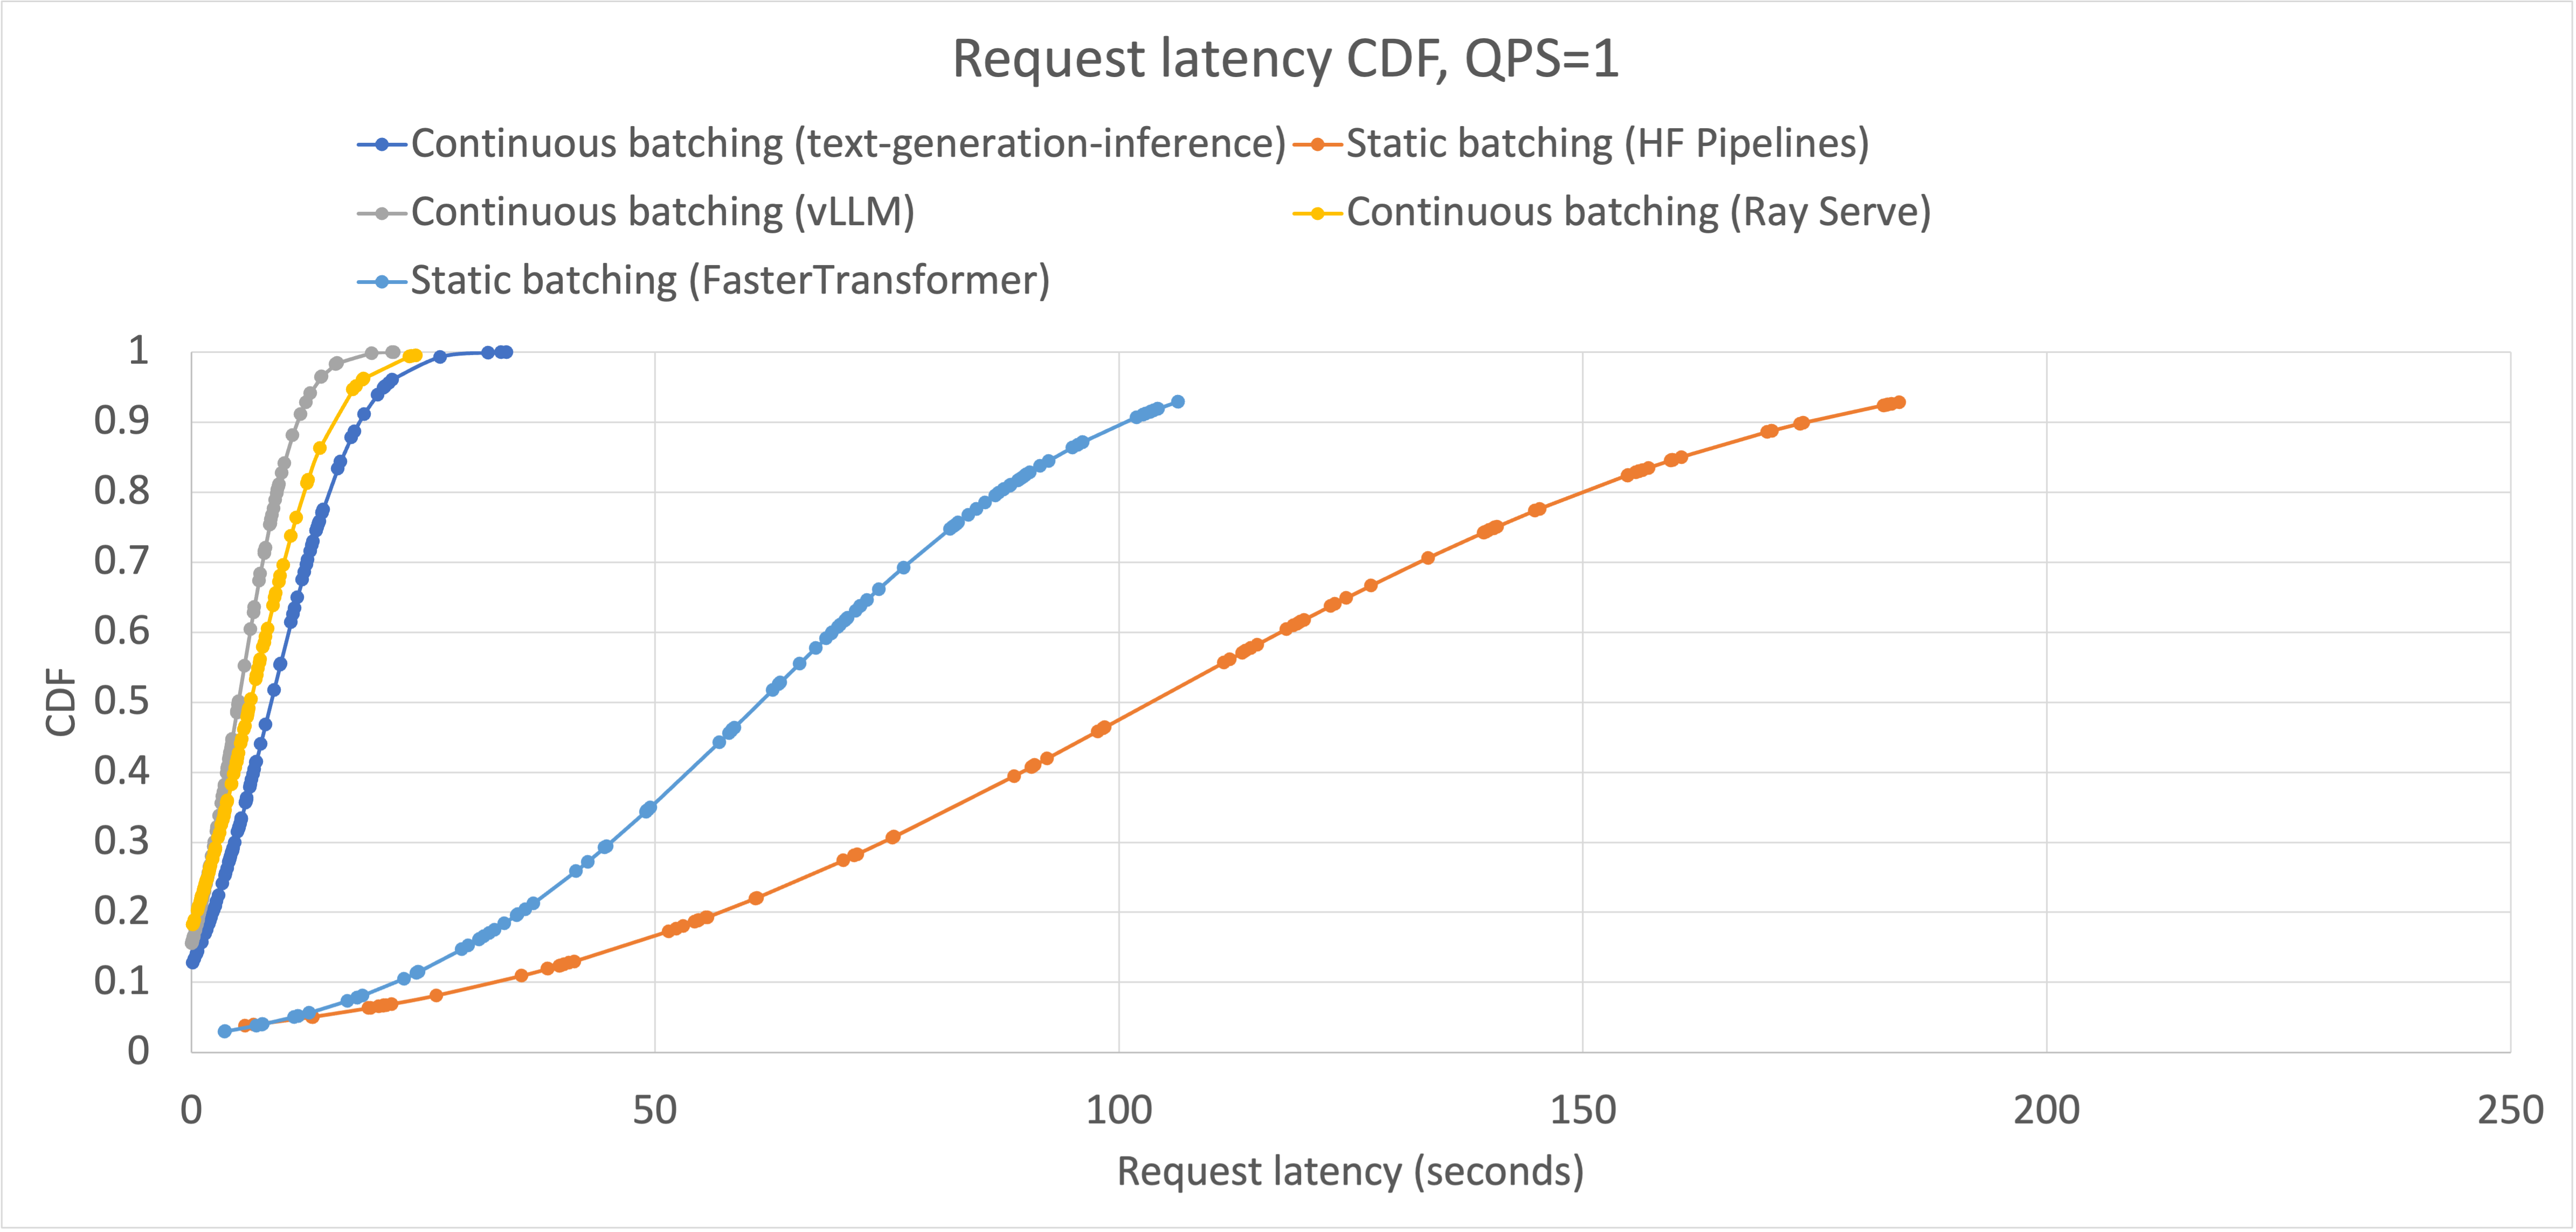
Scaling LLM inference with Ray and vLLM
Unleashing Efficiency: Benchmarking the Power of TensorRT LLM
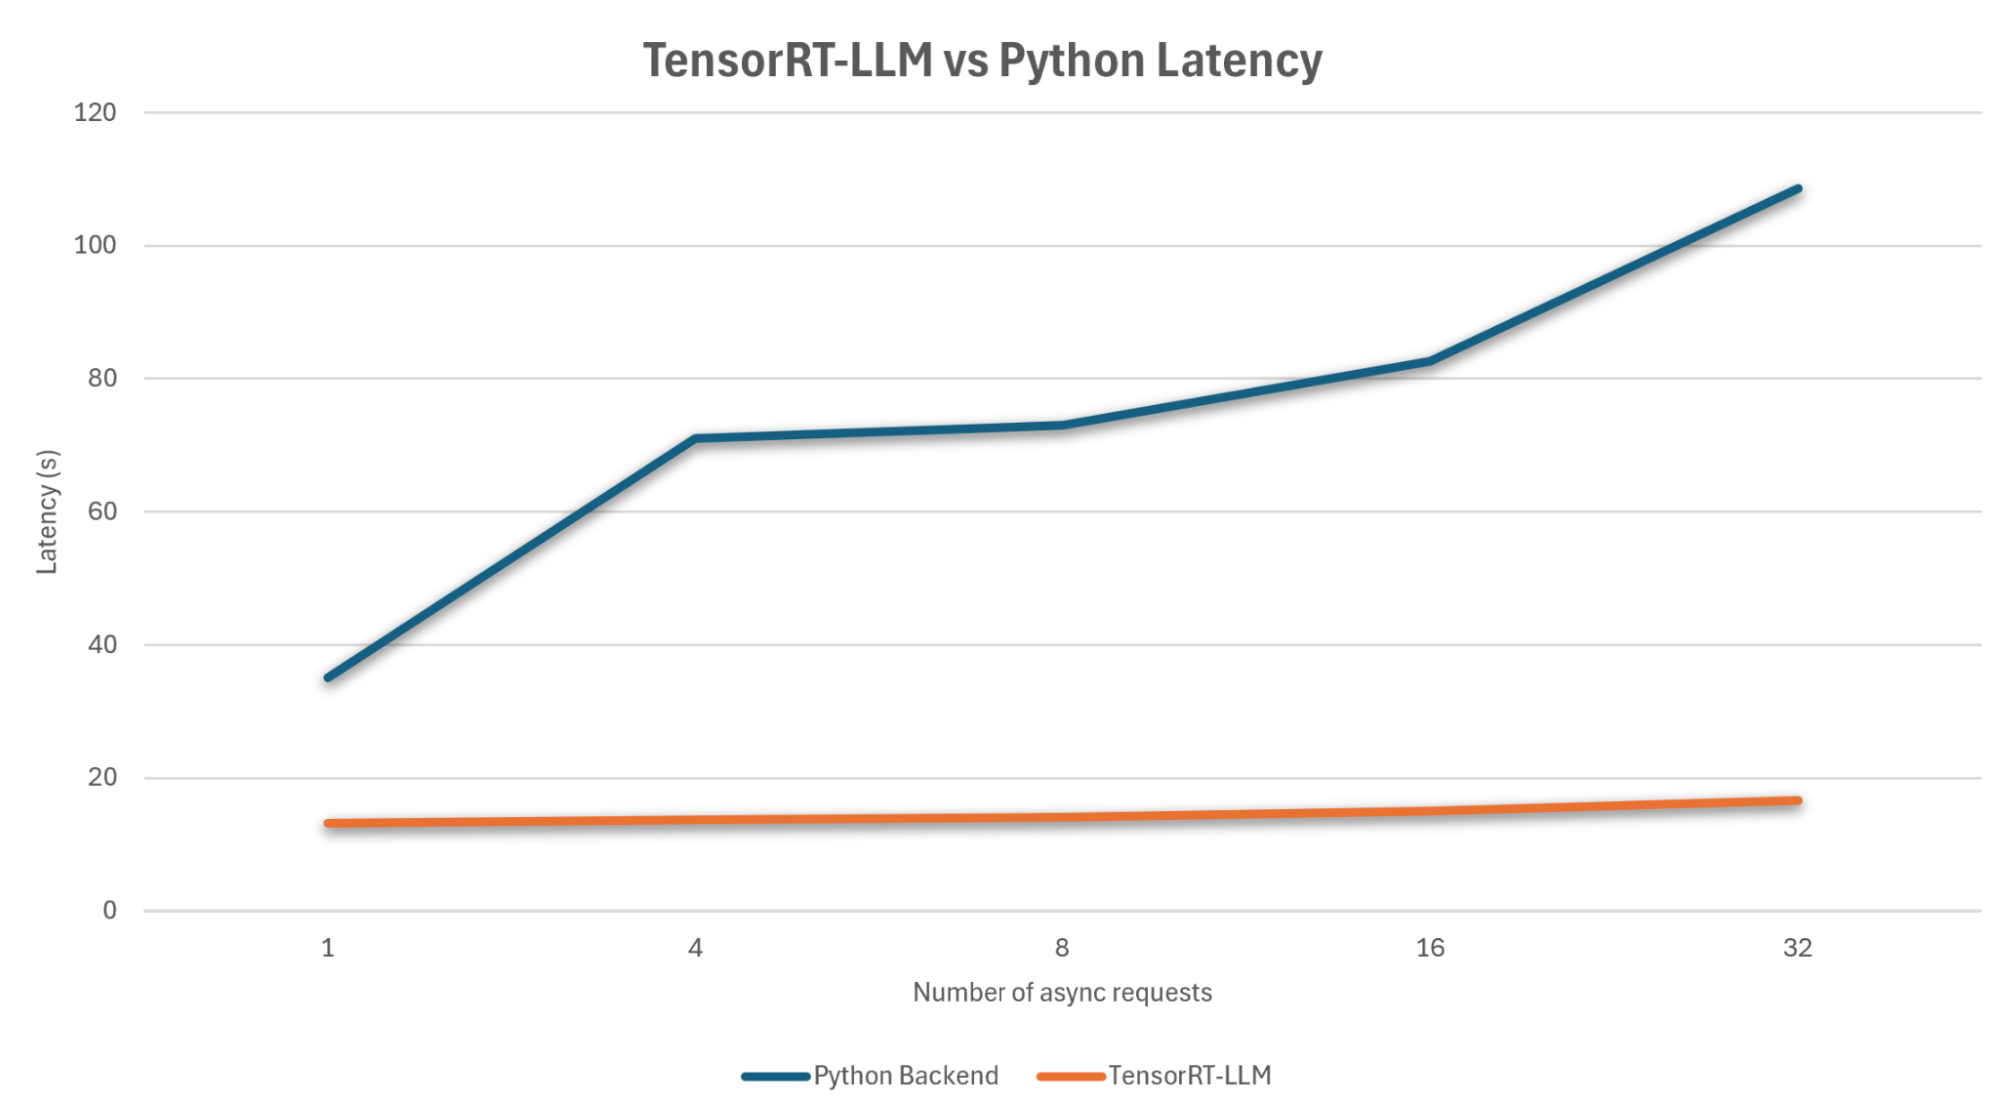
Accelerating Hebrew LLM Performance with NVIDIA TensorRT-LLM - NViNiO ...
Conceptual map of the cognitive game Cognitive Game or Cognitive ...
Accelerating Hebrew LLM Performance with NVIDIA TensorRT-LLM | NVIDIA ...
Prompt Attack Detection with LLM-as-a-Judge and Mixture-of-Models
Building a sovereign AI RAG solution with self-hosted LLMs, Qwen3 and vLLM
Latency-Response Theory Model: Evaluating Large Language Models via ...
Fast, Secure and Reliable: Enterprise-grade LLM Inference | Databricks
认识AnythingLLM:一款全栈应用程序,将您的内容转化为丰富的数据,以增强大型语言模型LLMs的相互作用 - 小猪AI
Conduct your own LLM endpoint benchmarking - Azure Databricks ...
[2504.11320] Optimizing LLM Inference: Fluid-Guided Online Scheduling ...
Semantic Attacks on Tool-Augmented LLMs: Securing the Model Context ...
Arm Community
Examples — scikit-learn 0.17.dev0 documentation
MatplotLLM: An /LLM assisted/ Data Visualization Framework
LLM Inference Efficiency | NexT
Event-Driven AI Workflows in Serverless Computing: Enabling Real-Time ...
Optimizing AI Performance: A Guide to Efficient LLM Deployment
Task: Read Paper, Implement and Evaluate FAST - Archlab SimpleSSD Project 4
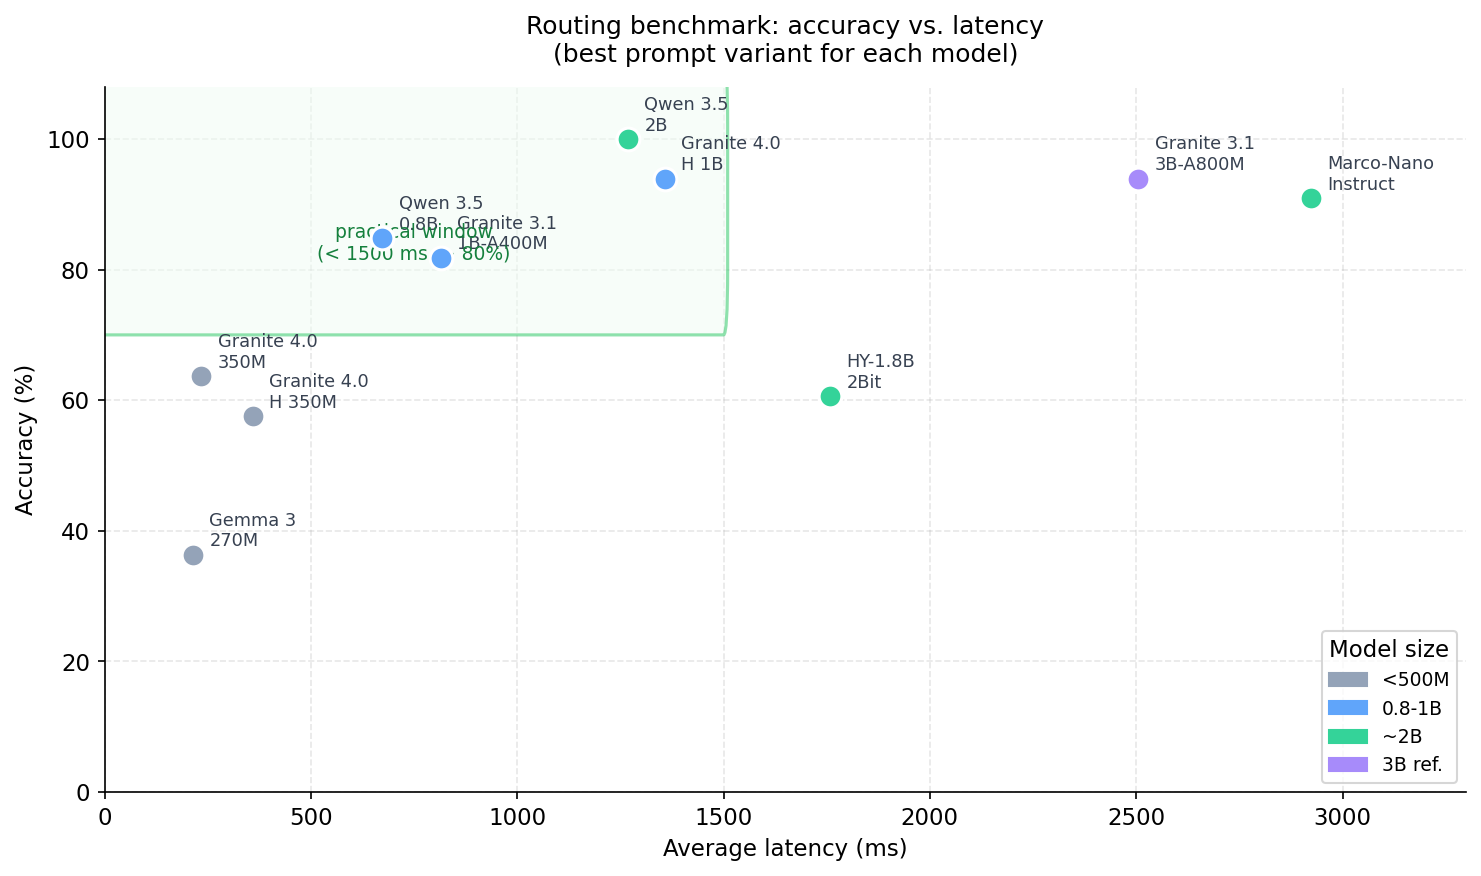
Prompting tiny LLMs: when structure helps and when it backfires ...
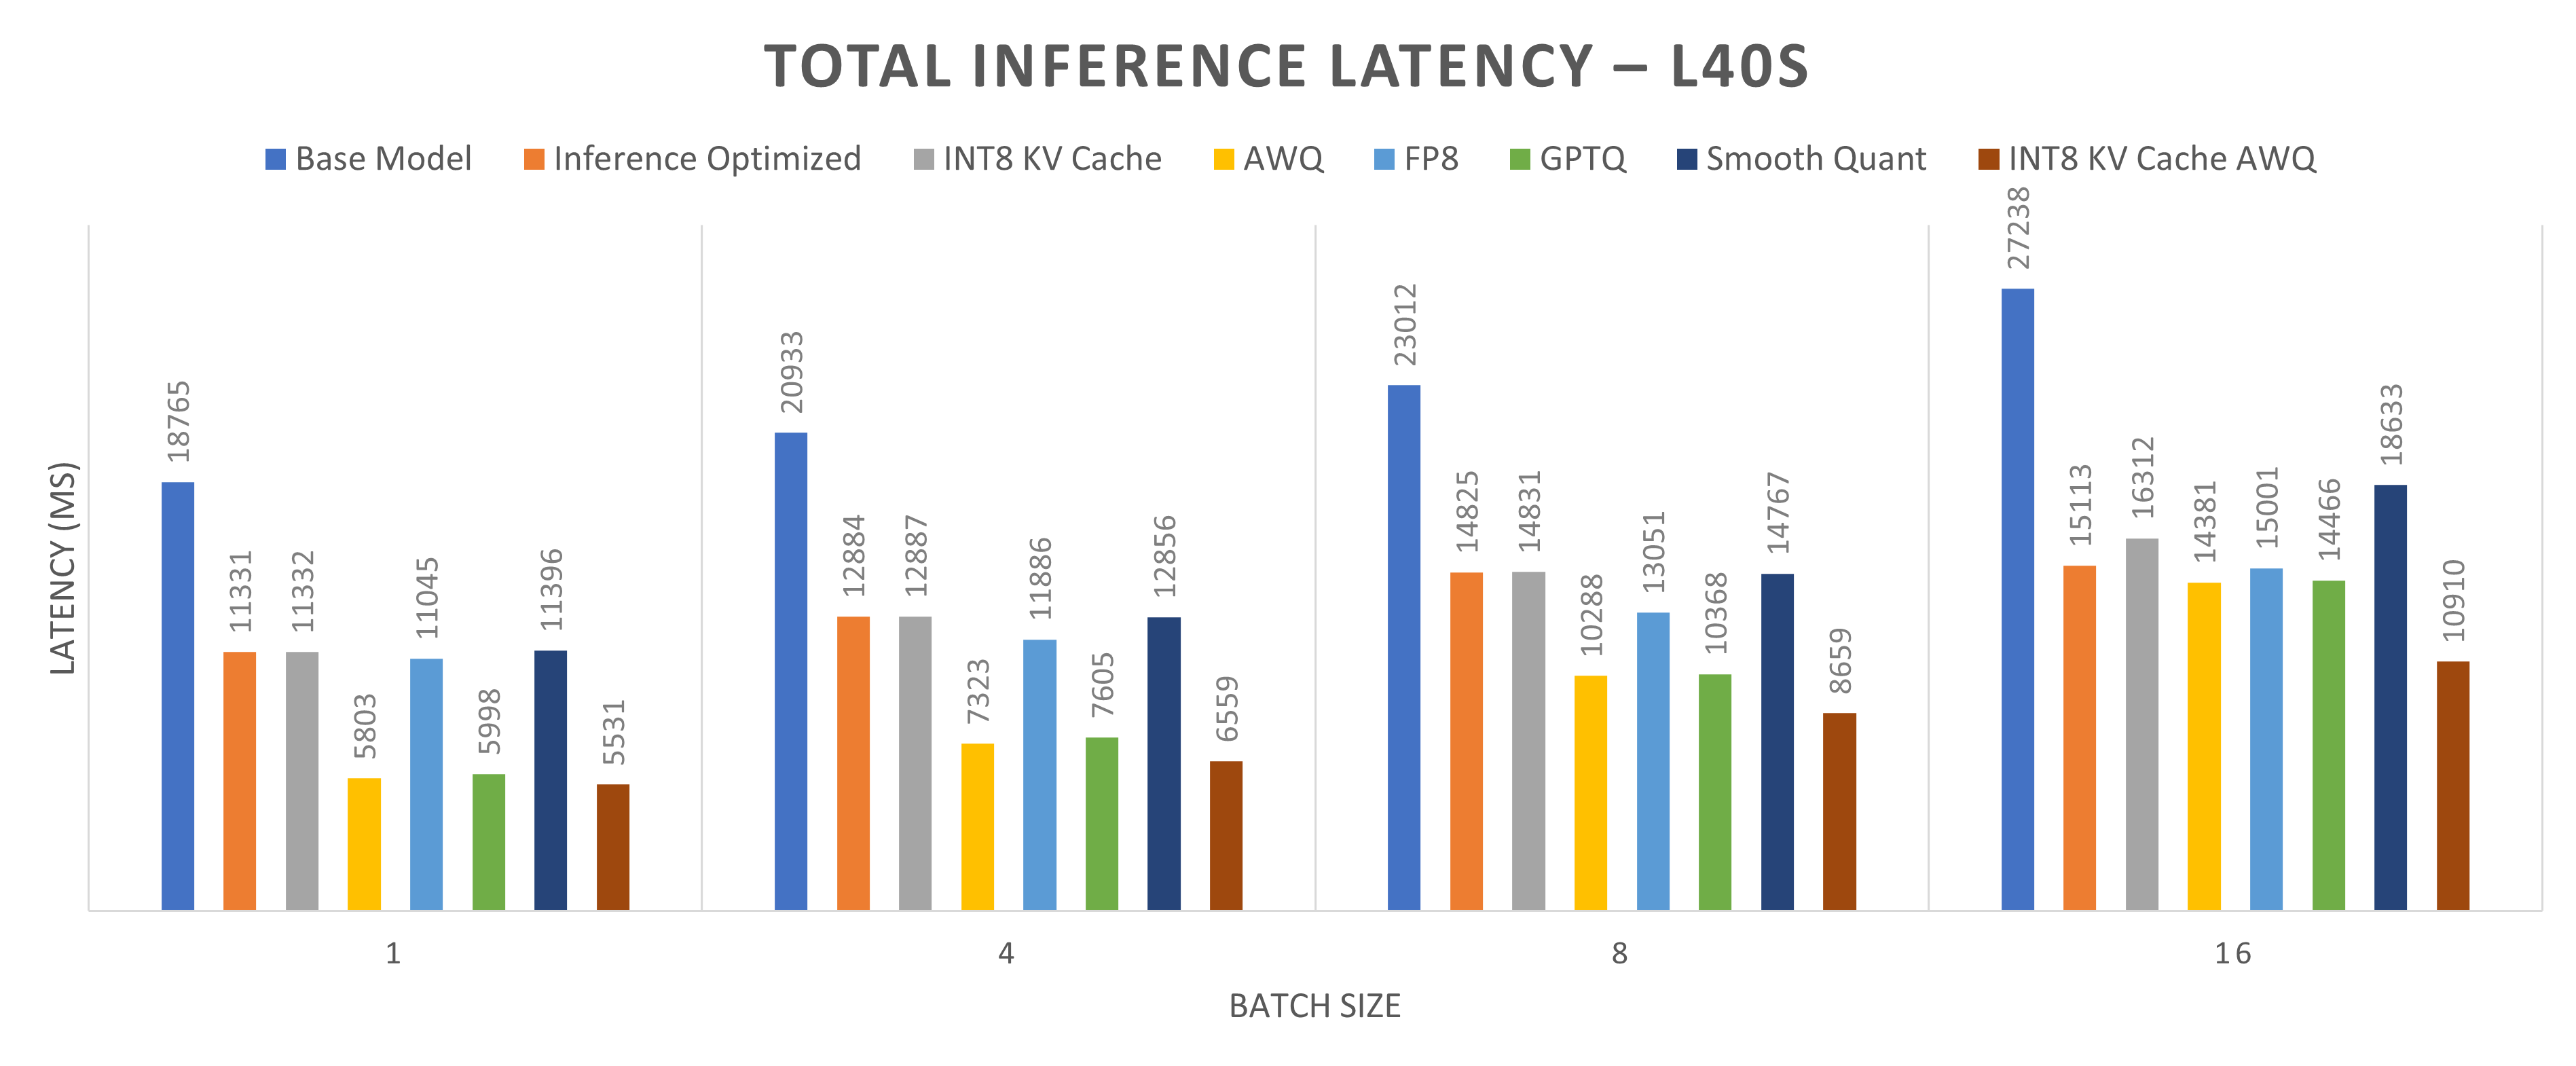
Unlocking LLM Performance: Advanced Quantization Techniques on Dell ...
New Client-Side Evaluation SDKs | Flipt Blog
The Ultimate Guide to LLM Experimentation and Development in 2024 ...
Advancing Multi-Robot Networks via MLLM-Driven Sensing, Communication ...
Working with Context Cores | TrustGraph
Introducing the First Hallucination-Free LLM | Pinecone
LiteLLM Alternatives : When Accuracy, Latency, and Ops Start to Hurt ...
8.2. Computational Performance — scikit-learn 1.5.2 documentation
Designing LLM-Powered Intelligent Interfaces and Optimizing User ...
From fixations to measures – DevStart
Knowledge Graph and LLM Integration: Benefits & Challenges
Medium
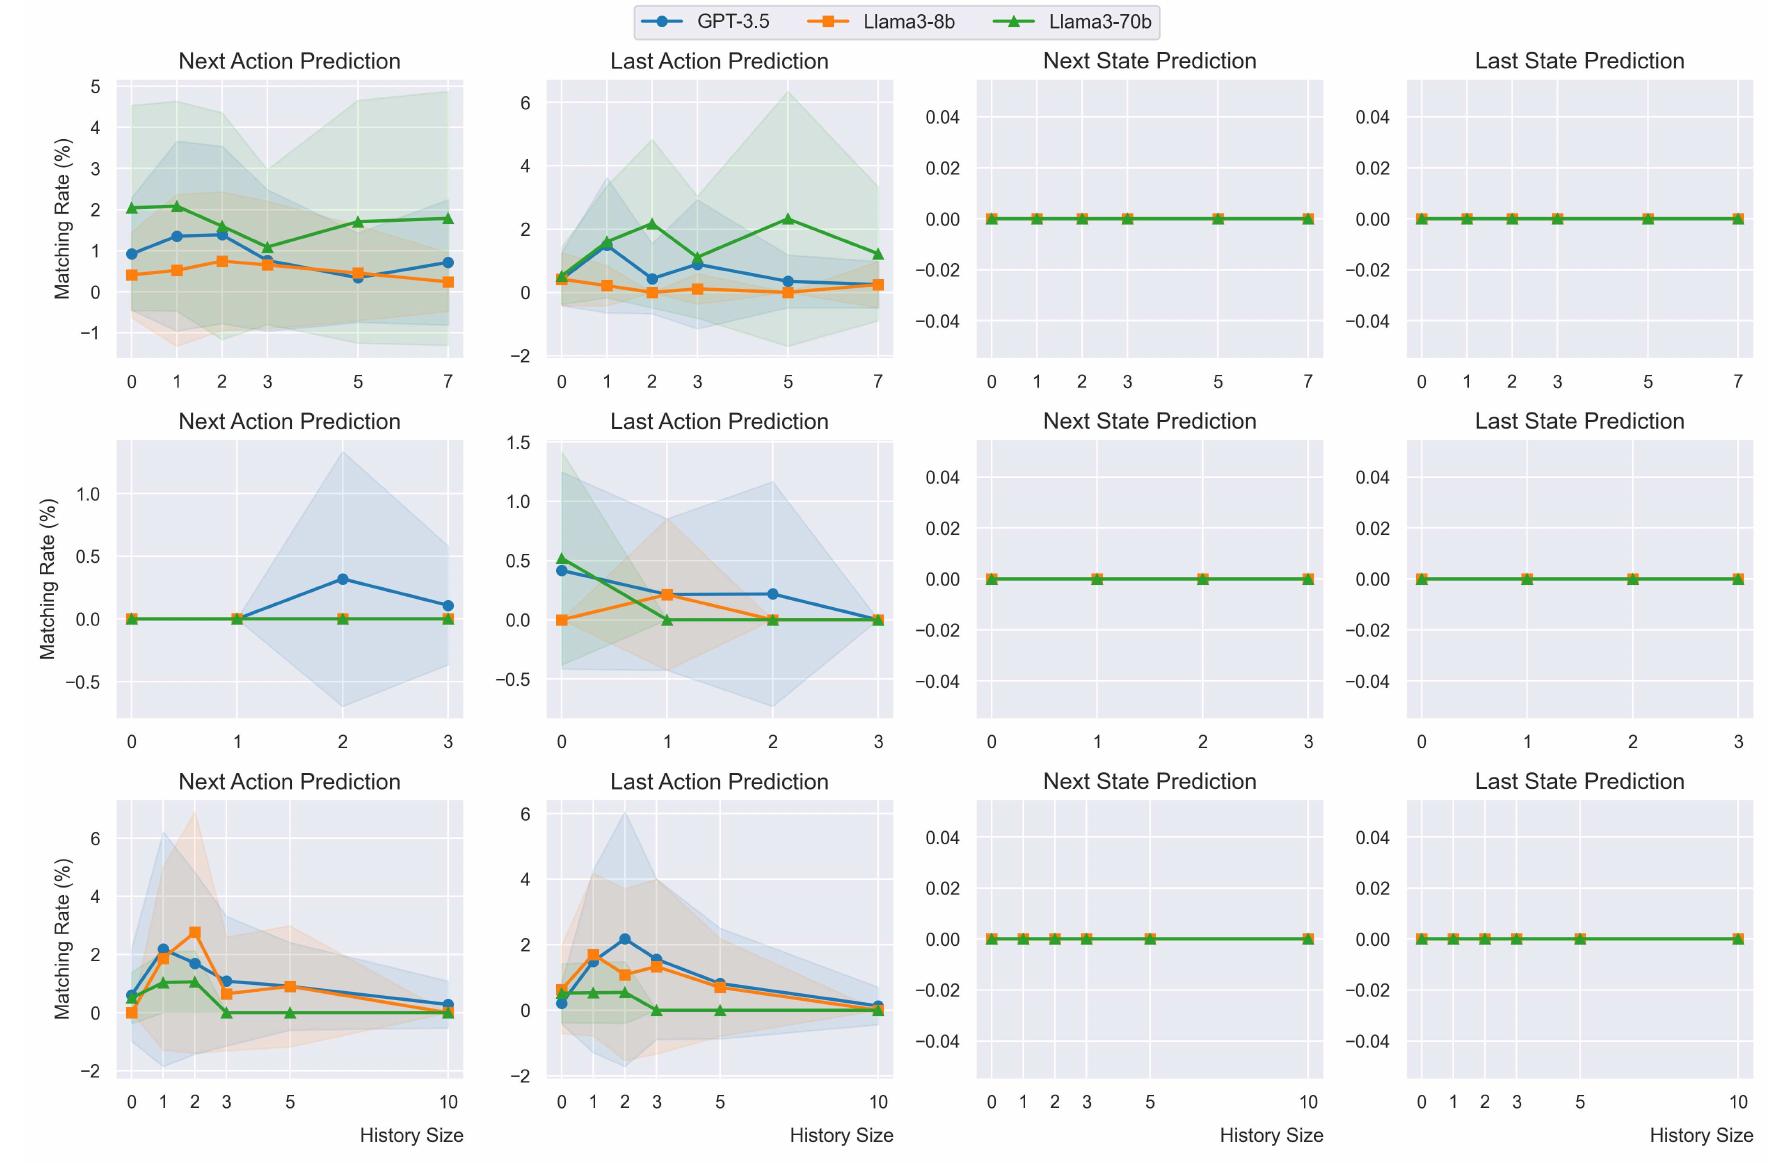
Comparative plots of llms’ performance on the fetch-series
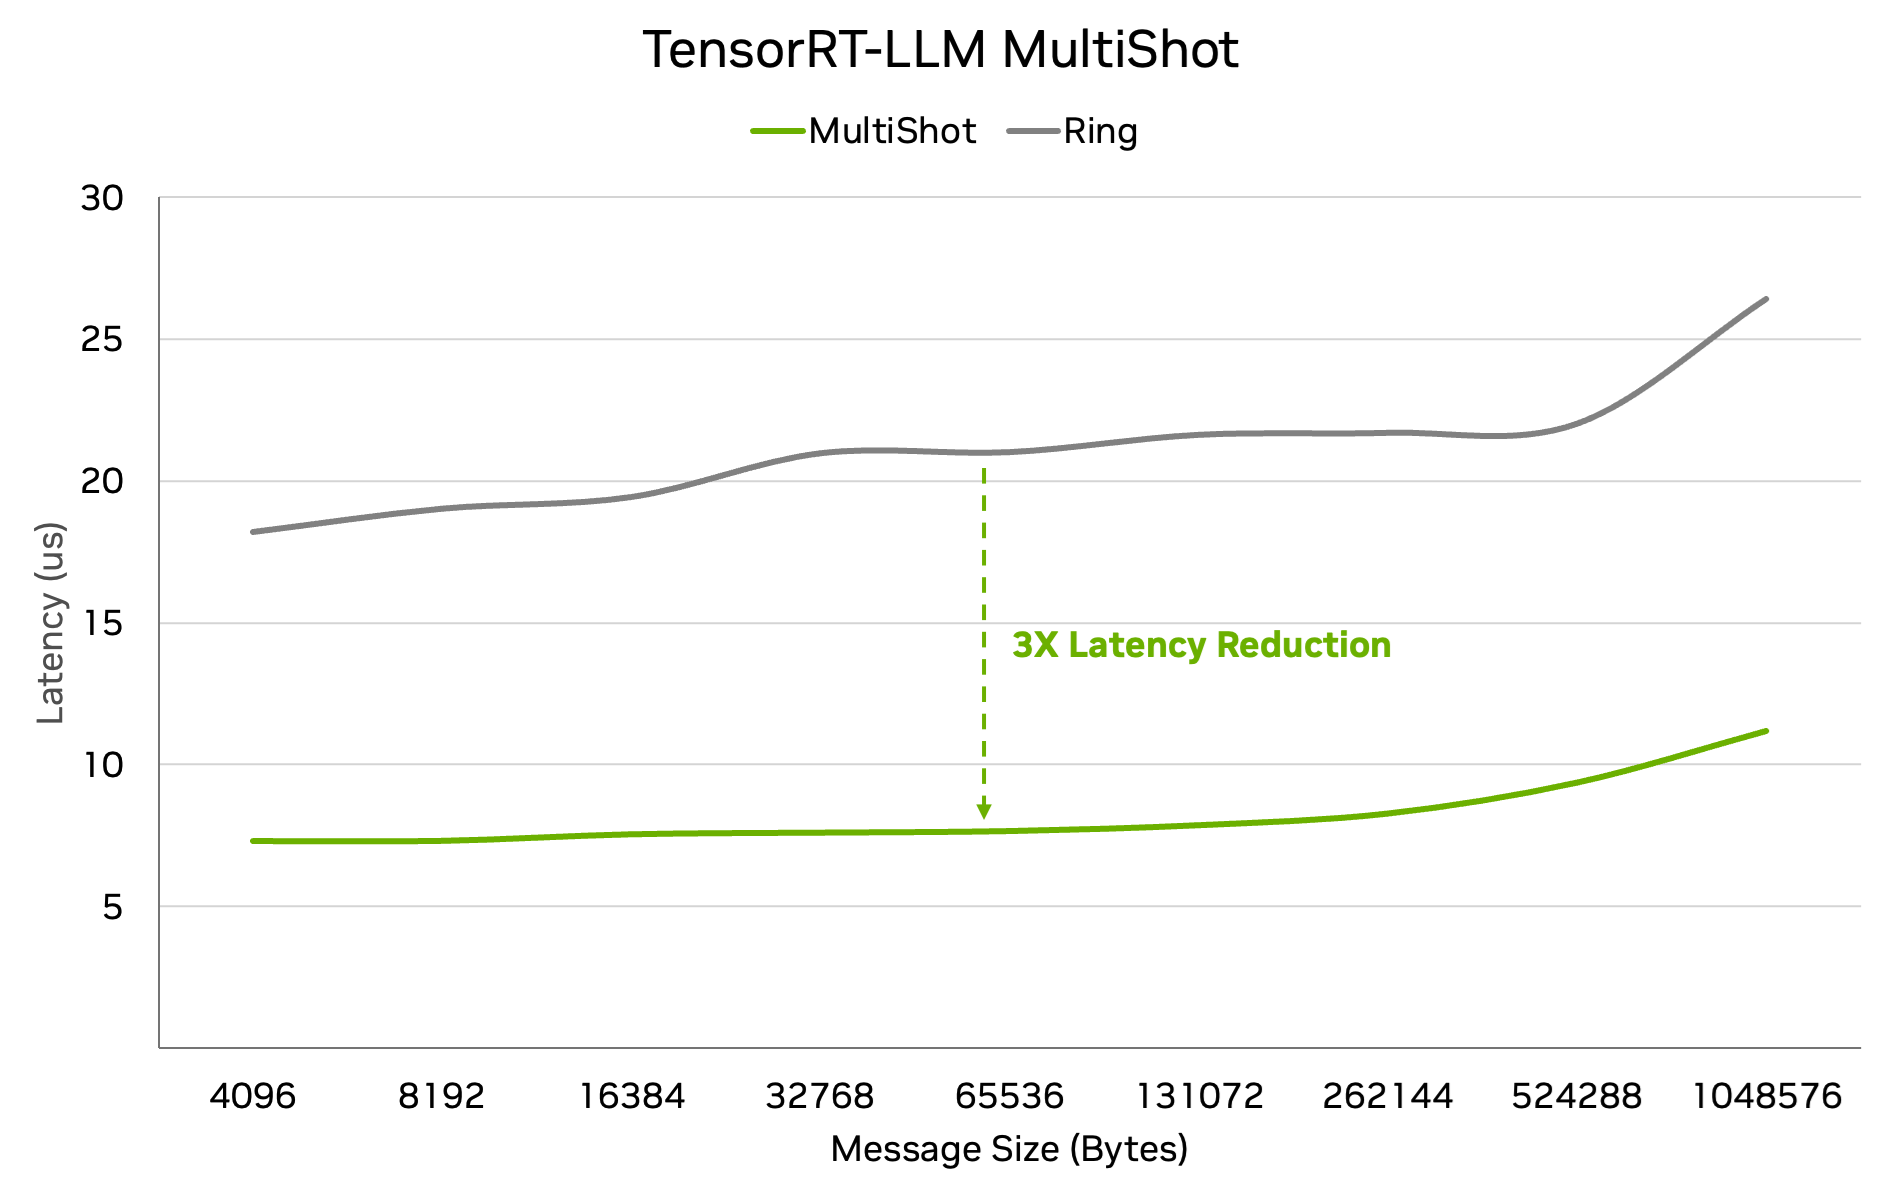
3x Faster AllReduce with NVSwitch and TensorRT-LLM MultiShot | NVIDIA ...
Large language model inference optimizations on AMD GPUs — ROCm Blogs
PiML Toolbox
Towards a Bio-inspired Real-Time Intrusion Detection in the Smart Grid ...
Simulation Performance Plots - MATLAB & Simulink
Step-by-Step Guide to Build observability into an LLM application | TO ...
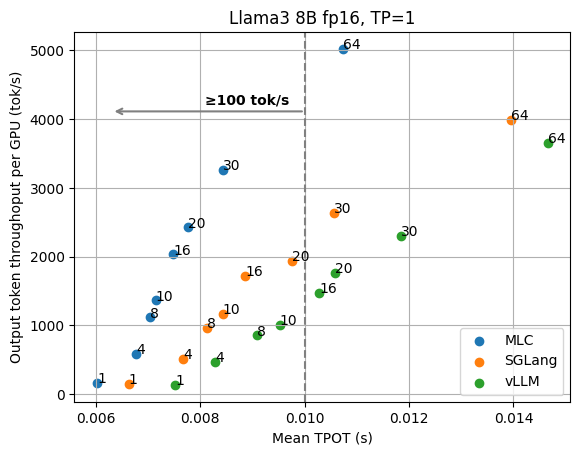
MLC | Optimizing and Characterizing High-Throughput Low-Latency LLM ...
Addressing GitHub’s recent availability issues - The GitHub Blog
LLM Video Games – Kshitij (Tjay) Dhyani